AMD says MEXT can retain 95% server performance with half the DRAM
AMD says MEXT can cut server DRAM use by 20% to 75% while keeping much of the performance, using flash and AI to offload cold memory pages. The company has deployed it on 145 servers and plans to reach 2,000 next year.
AMD has outlined how MEXT, a predictive memory engine, can reduce the physical DRAM needed in servers while keeping most performance. MEXT claims upwards of 99% of the performance of a full-DRAM system while running with as little as 25% of physical DIMMs. The technology moves cold memory pages to flash storage and uses an AI model to bring them back before they are needed.
How MEXT moves memory to flash
MEXT offloads cold memory pages to flash storage, while the missing memory still registers as installed DRAM to the operating system. Because flash is slower than DRAM, MEXT uses an AI model to predict which pages will be needed and move them back before they are required. AMD says the model can train in under a second when first deployed, runs on one EPYC core without a GPU, and continues training as the workload progresses. MEXT is deployed as a Linux kernel module that works with any Linux distribution, and it uses an ensemble of AI models led by a transformer-based large language model.
AMD's internal performance claims
In some internal workloads, such as Synopsys PrimeTime, AMD says servers running at 50% DRAM capacity retain 95% of the performance of a full server, while 25% capacity maintains 80% of performance. In a three-node Azure cluster with 5th-gen EPYC CPUs, AMD says MEXT delivered 99% of full-cluster performance at 50% DRAM capacity on the Spark SQL workload from the TPC-DS benchmark. For agentic AI, AMD claims 99% of full-server performance at 50% memory capacity and 85% at 25% capacity across a five-agent concurrent geomean. For a memory-hungry agent, AMD claims 90% performance at 50% capacity and 88% at 25% capacity.
Deployment and rollout
AMD has deployed MEXT internally on 145 servers and says it will expand to 2,000 servers next year. It has also announced a partnership with HPE to bring MEXT to customers. Phase 1 includes some EPYC Venice servers with a MEXT Ready badge and a dedicated NVMe drive or bay for offload. Phase 2 will bring MEXT licenses and the RAM View application to those servers, but AMD has not said when Phase 2 will begin.
Workloads and limits
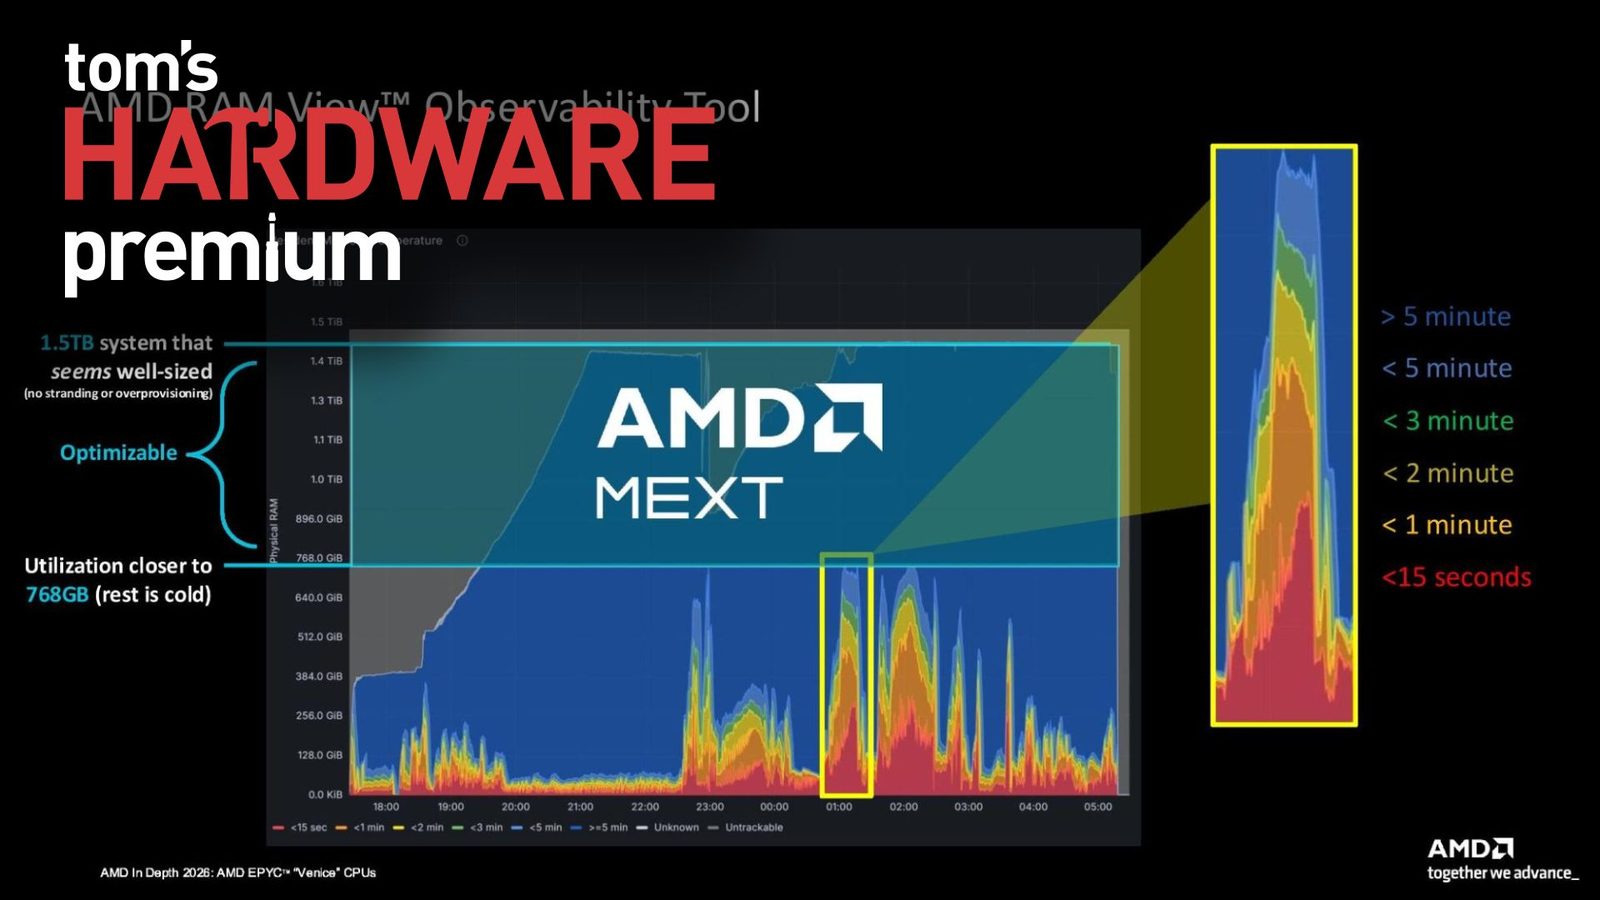
AMD is initially applying MEXT to critical EDA applications it uses internally, including Synopsys PrimeTime, while also optimizing agentic AI, database, and media and entertainment workloads. The company says many workloads can reduce capacity by around 20% to 25%, while higher reductions become more specialized and carry larger performance differences. AMD says RAM View shows which pages are hot and cold; in one generalized example, a system with 1.5 TB of memory showed near-full utilization, with around half of pages not touched in five minutes or more at any given time. AMD has not clarified the workload for that example, and it has not shared footnotes for some benchmark slides.
Sources: Tom's Hardware · The Register
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.