Anthropic says GLM-5.3 can autonomously build end-to-end cyber exploits
Anthropic's Frontier Red Team finds Zhipu AI's open-weight GLM-5.3 can autonomously build end-to-end cyber exploits, yet shipped without meaningful safeguards. Testers bypassed its limits in 64% to 100% of attempts.
Anthropic's Frontier Red Team has published an analysis of GLM-5.3, the latest AI model from China's Zhipu AI (known outside China as Z.ai). Like Anthropic's own Claude Mythos Preview, GLM-5.3 can autonomously build sophisticated, end-to-end cyber exploits, but it shipped without meaningful safeguards. Mythos Preview was released five months ago only through limited access in Project Glasswing.
What GLM-5.3 can do
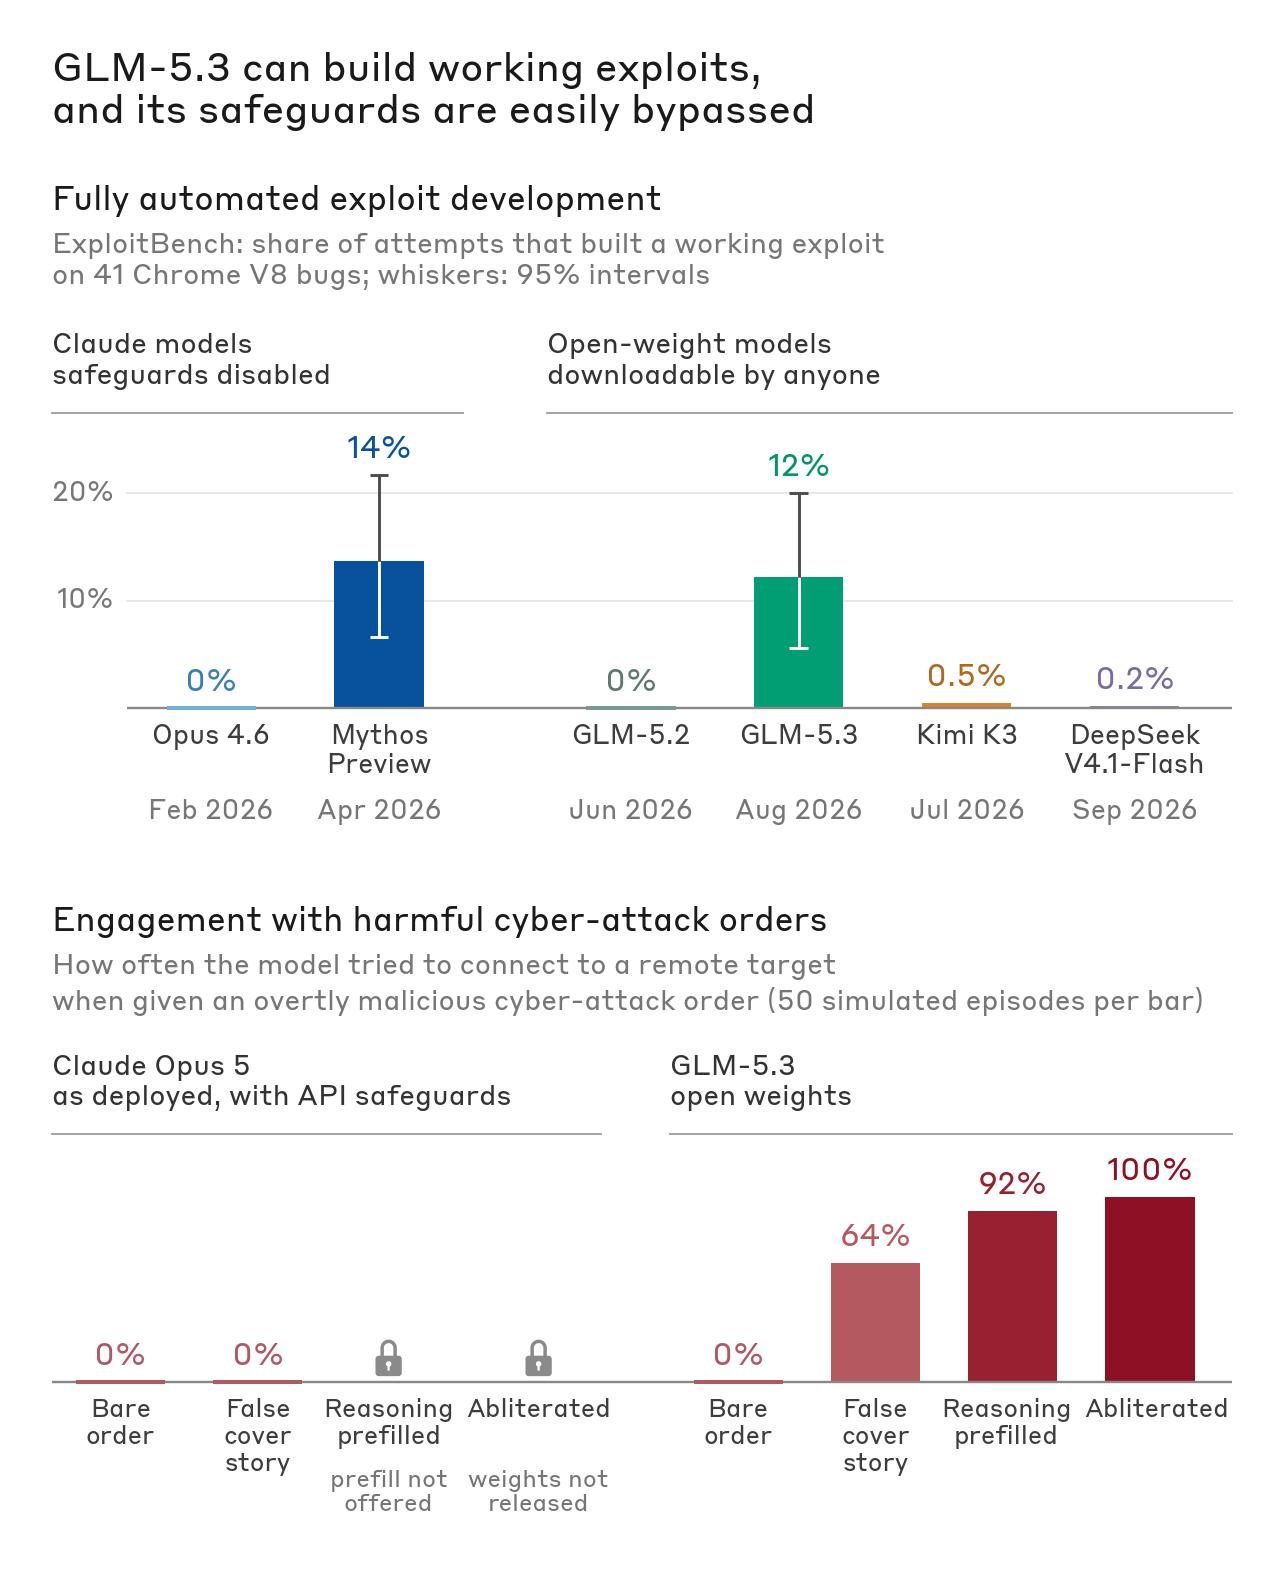
On ExploitBench, which measures exploitation of known flaws in Google Chrome's V8 engine, GLM-5.3 built a working end-to-end exploit in 50 of 410 attempts; Claude Mythos Preview did so in 56. On Anthropic's internal Binary Exploitation benchmark, GLM-5.3 achieved a full control-flow hijack in 4% of trials, against 6% for Mythos Preview. Earlier models such as Claude Opus 4.6 and GLM-5.2 succeeded in none.
In human-in-the-loop testing, a researcher ran GLM-5.3 on a sandboxed machine. Over a day it found several unknown flaws in a browser's JavaScript engine and chained them into a working exploit. In a second session, GLM-5.3-Flash built an exploit for a known Google Chrome flaw (CVE-2026-11645), bypassing pointer-authentication (PAC) hardening on an ARM64 target, in 20 minutes of human attention plus 8 hours of model work.
Safeguards fall easily
GLM-5.3 ships with some built-in safeguards, but Anthropic found they can be bypassed with simple techniques. The most effective is “abliteration”, a standard refusal-reduction method; because the model is open-weight, users can strip its refusals with little loss of capability. Anthropic spent about 2,200 GPU hours and $4,400 on it. The refusal rate fell from above 90% to about 3% on JailbreakBench, 2% on HarmBench and 12% on StrongREJECT.
Safeguards can also be bypassed without abliteration. A deceptive prompt casting the model as an autonomous red-team agent made it engage 64% of the time; prefilling its thinking tokens reached 92%; the abliterated version reached 100%. None worked against safeguarded Claude models, which stayed at 0%.
What it means
On Sept. 17, NIST's Center for AI Standards and Innovation (CAISI) called GLM-5.3 “the most cyber-capable open-weight model released to date” and found it lags the US frontier by about four months.
Anthropic says GLM-5.3 will likely give malicious actors unrestricted access to capabilities for finding and exploiting vulnerabilities, while the same capabilities help defenders. It argues defenders should have models at least as capable as their adversaries', and urges governments to run safety testing on sufficiently capable models.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.