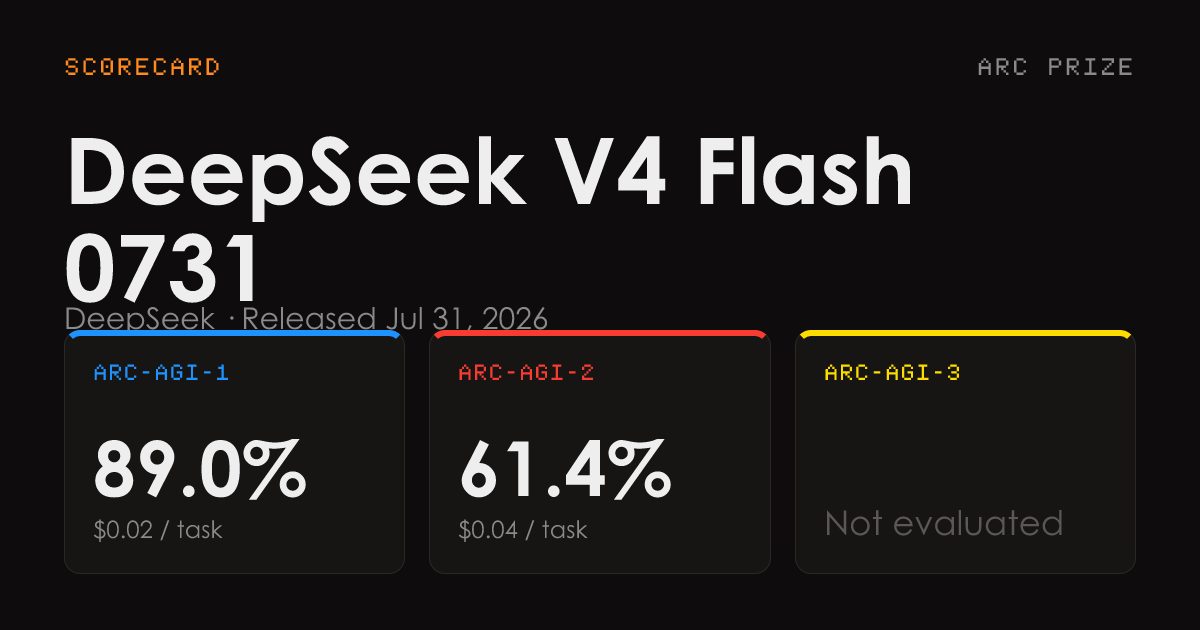
DeepSeek V4 Flash 0731 scores 89% on ARC-AGI-1 and 61.4% on ARC-AGI-2
ARC Prize has published verified results for DeepSeek V4 Flash 0731: at maximum reasoning effort the model reaches 89.0% on the ARC-AGI-1 Semi-Private set and 61.4% on the harder ARC-AGI-2, at $0.02–$0.04 per task.
Four reasoning levels, verified
ARC Prize has published verified results for DeepSeek V4 Flash 0731, the model DeepSeek released on July 31, 2026. At maximum reasoning effort it scores 89.0% on the ARC-AGI-1 Semi-Private set and 61.4% on ARC-AGI-2 Semi-Private, at a cost of $0.02 and $0.04 per task respectively.
The scores track how much reasoning effort the model is allowed to spend. At the "High" setting it reaches 87.0% on ARC-AGI-1 and 56.0% on ARC-AGI-2; at "Low", 84.0% and 46.0%. With reasoning disabled entirely, performance drops to 11.8% and 2.1%.
Task-by-task breakdown
The results page also breaks the ARC-AGI-2 Public Eval down to the level of individual puzzles, showing pass and fail marks for each of the 120 tasks across all four variants. The pattern is uneven: some tasks are solved only at maximum effort, while others defeat every setting. No ARC-AGI-3 scores are listed for the model.
Why the spread matters
ARC-AGI is designed to measure abstract reasoning on novel puzzles rather than the recall of material seen during training, and the second edition of the benchmark is deliberately harder than the first. The distance between the "None" and "Max" rows — 2.1% versus 61.4% on ARC-AGI-2 — is a direct measure of how much of the result comes from inference-time reasoning rather than raw capability. The cost figures are part of the story as well: at $0.04 per ARC-AGI-2 task, a strong score stays within reach of ordinary experimentation budgets.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.