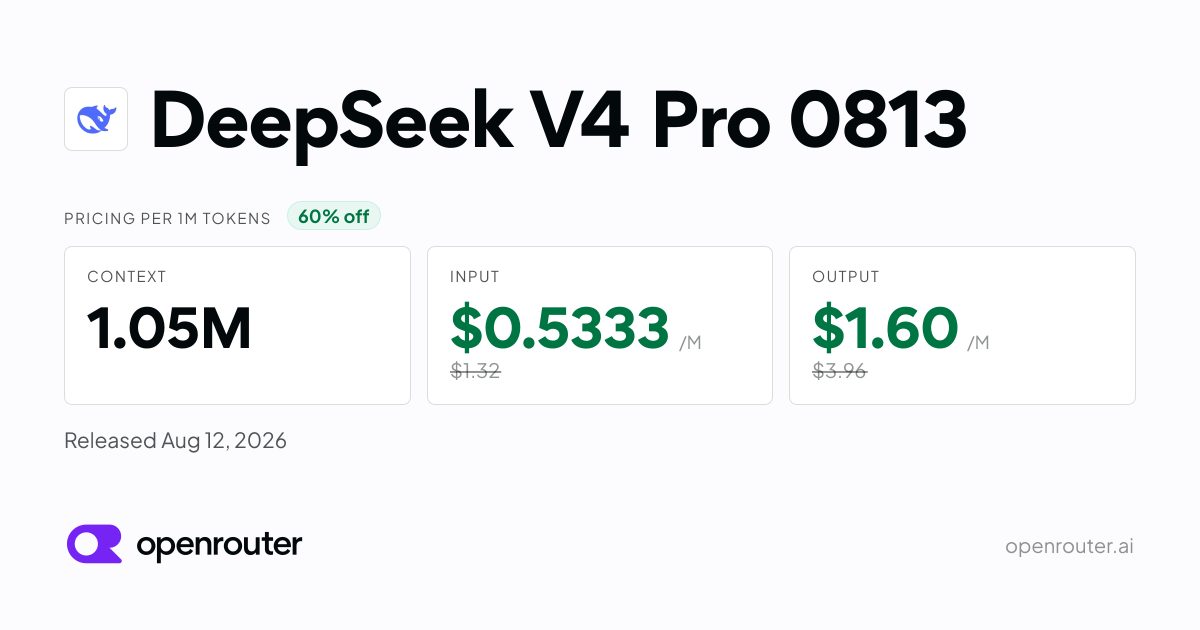
DeepSeek V4 Pro 0813: 1M-Token Context, $0.66/M Input, 17 Providers on OpenRouter
DeepSeek's V4 Pro reaches general availability: a mixture-of-experts model with a one-million-token context window, priced at $0.66 per million input tokens.
DeepSeek has published the general-availability release of DeepSeek V4 Pro, listed on OpenRouter as DeepSeek V4 Pro 0813. The model is a large-scale mixture-of-experts system with a context window of 1,048,576 tokens — roughly one million — and support for up to 384,000 completion tokens in a single response.
Pricing and capabilities
On OpenRouter, the model is priced at $0.66 per million input tokens and $1.98 per million output tokens, with a separate cache-read rate of $0.022 per million tokens. It accepts tools and tool_choice for function calling, and supports response_format for JSON output, though without JSON-schema enforcement. Weights are published on Hugging Face under deepseek-ai/DeepSeek-V4-Pro-0813.
Seventeen providers, one endpoint
Requests are served by 17 providers, among them DeepSeek itself, StreamLake, Alibaba Cloud International, GMICloud, DeepInfra, CoreWeave, NextBit and Sail Research, with automatic failover between them and provider routing that lets users pin or exclude a given operator. OpenRouter reports a best P50 throughput of 77 tokens per second and a best P50 latency of 0.48 seconds across endpoints, plus 100% uptime and 99.46% availability over the past three days.
Benchmarks
In the evaluations listed on the model page, GPQA Diamond scores range from 86.0% to 90.7% depending on the serving provider, and reach 88.6% on automatic routing. On TAU-Bench, SiliconFlow reports 79.9% and Baseten 74.7%. OpenRouter notes that availability over the last 24 hours was 99.56% with routing, against 96.94% without it — a reminder that provider diversity, not just the model, shapes the user experience.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.