Fireworks AI releases Ember-1, a Kimi K3 variant that thinks in 40% fewer tokens
Fireworks Research has released Ember-1, a specialized model built on Kimi K3. The company says it keeps the base model's answer quality while using roughly 40% fewer tokens.
Fireworks AI has released Ember-1, a specialized model built by its Fireworks Research team on top of Kimi K3. In an announcement published on 23 September 2026, the company says Ember-1 matches Kimi K3's answer quality while using 40% fewer tokens, by dropping reasoning that does not affect the final answer.
Why reasoning models get expensive
Reasoning models such as Kimi K3 spend most of their generated tokens, sometimes more than 90%, on internal thinking rather than the answer, the company writes, and multi-turn agentic workloads make it worse: every turn replays earlier reasoning into the context, so the context grows roughly quadratically with the number of turns. Lowering Kimi K3's reasoning effort did not fix it, because weaker settings gave up too much quality. So the model had to learn to reason more efficiently: the team ran more than 50 training experiments and over 200 evaluations, and wrote new algorithms to shorten reasoning without losing accuracy.
Benchmarks and a Pareto frontier
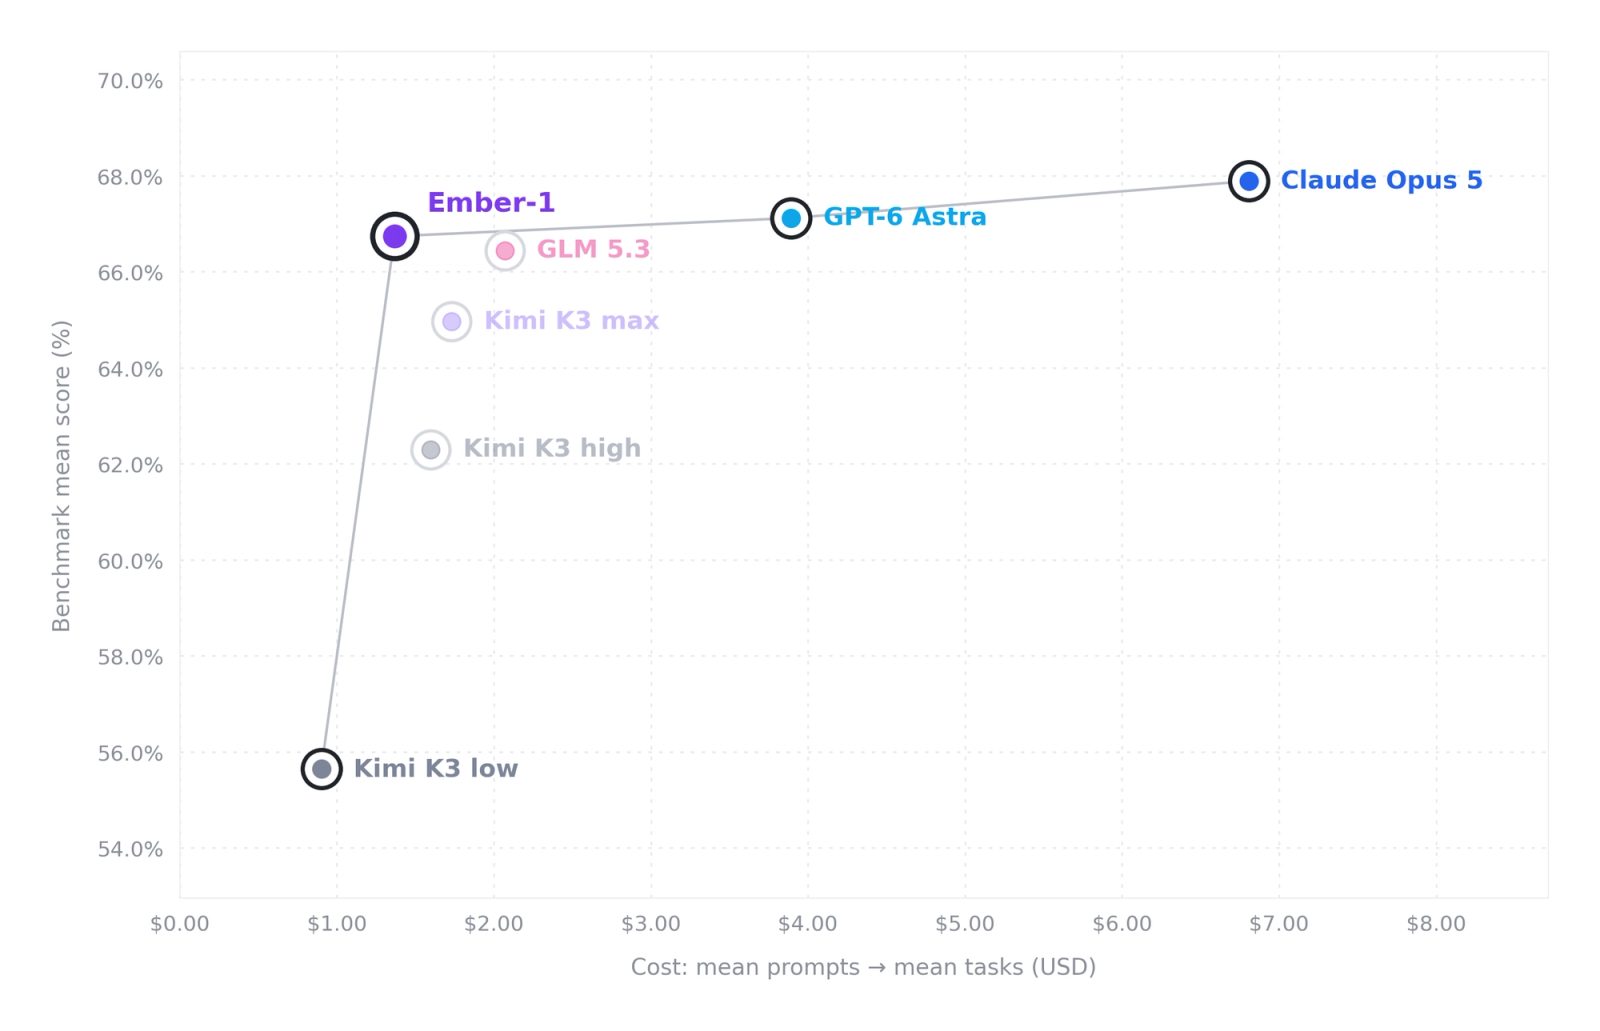
Across seven benchmarks and two customers' production traffic, Fireworks found that Kimi K3's reasoning could be shortened by 35-50% without sacrificing accuracy. On Doximity's Bedside Bench, a physician-validated benchmark of 500 clinical cases across 10 categories, Ember-1 set a new Pareto frontier on cost per task among both open and closed models, including GPT-5.6 Sol, GPT-6 Astra and Claude Opus 5.
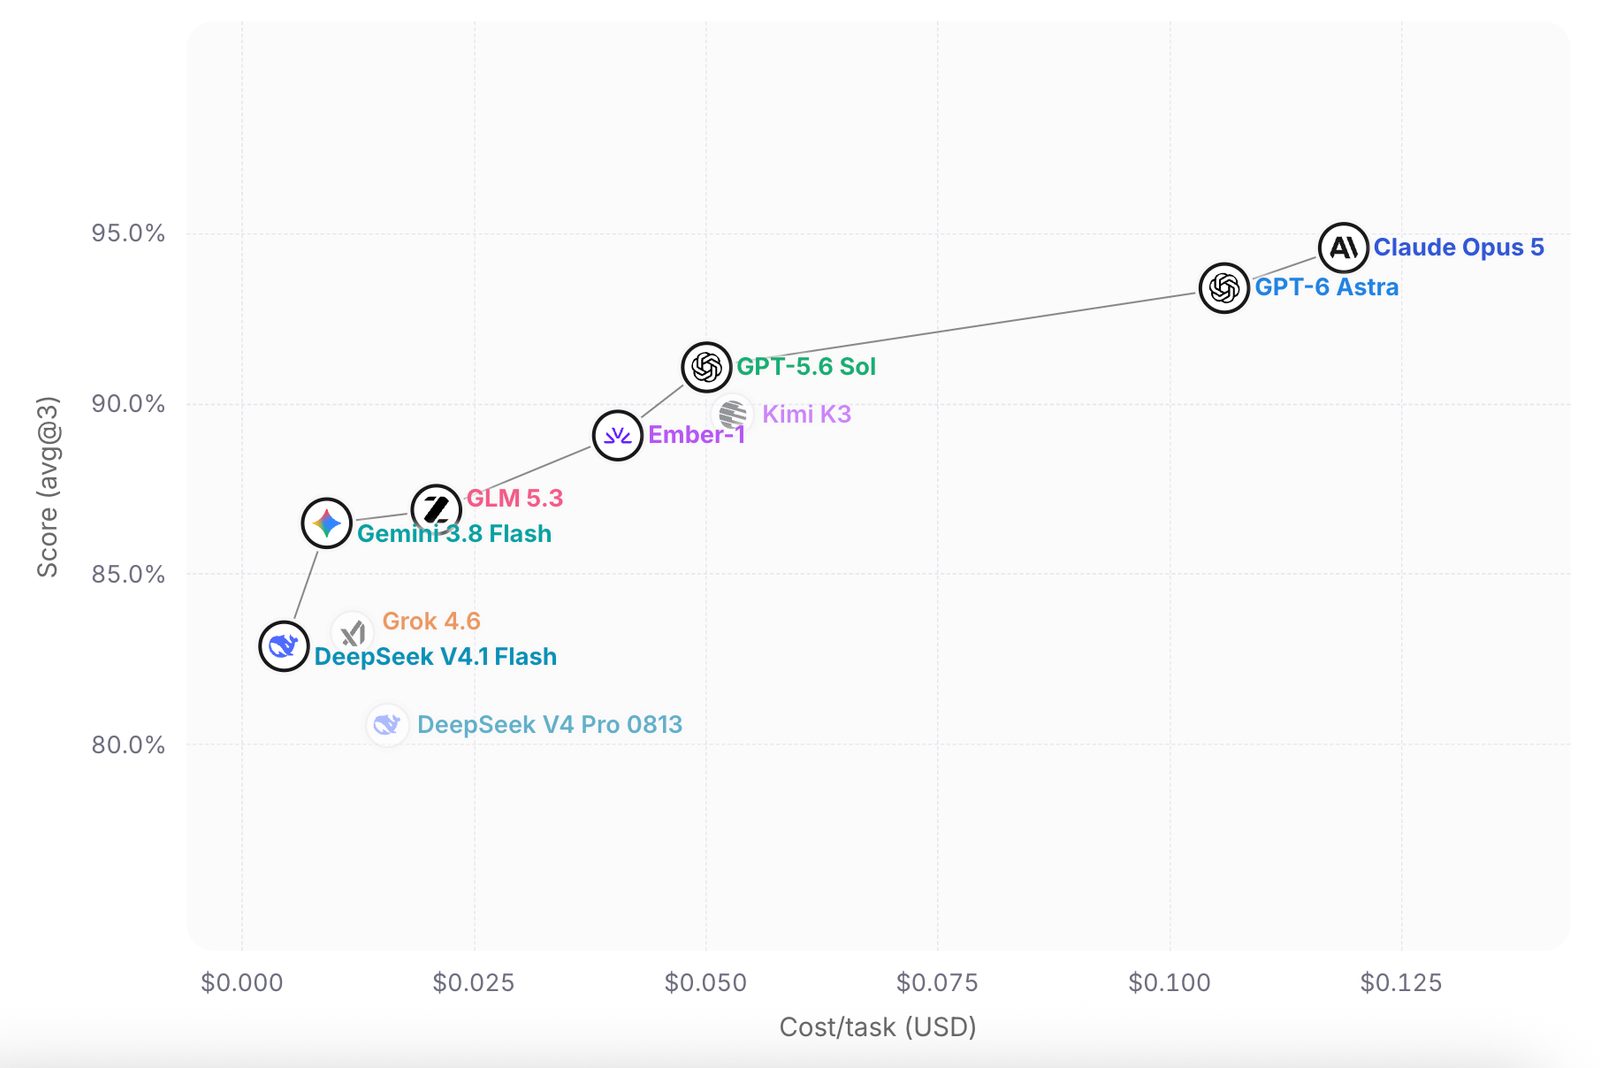
On individual benchmarks the results are close. Terminal Bench 2.1: 82.0% against 80.9%. DeepSWE 1.1: 75.2% against 66.4%. SWE-bench Verified: 92.2% versus 93.2%. SWE-Interact: 20.0% versus 21.3%. Fireworks says Ember-1 also dominates Kimi K3 at the model's low reasoning setting.
A/B tests, internal rollout and next steps
Two customers ran live A/B tests on production coding workloads and saw roughly 35% fewer tokens per task at comparable quality. In one test the average task score moved from 0.751 to 0.753 while output tokens fell from 49.3K to 29.9K, a 71.3% cut in reasoning tokens and 39% overall. Completion and failure rates held or improved, and one customer has moved Ember-1 into production with plans to replace the base model entirely.
Fireworks also switched its own developers to Ember-1 before showing it to customers, and reports “no news”: engineers did not notice the change. The model is rolling out as a serving option alongside the base Kimi K3 model as a research preview on Serverless. Training support is launching as well, for enterprises that want customized, token-efficient models on their own data.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.