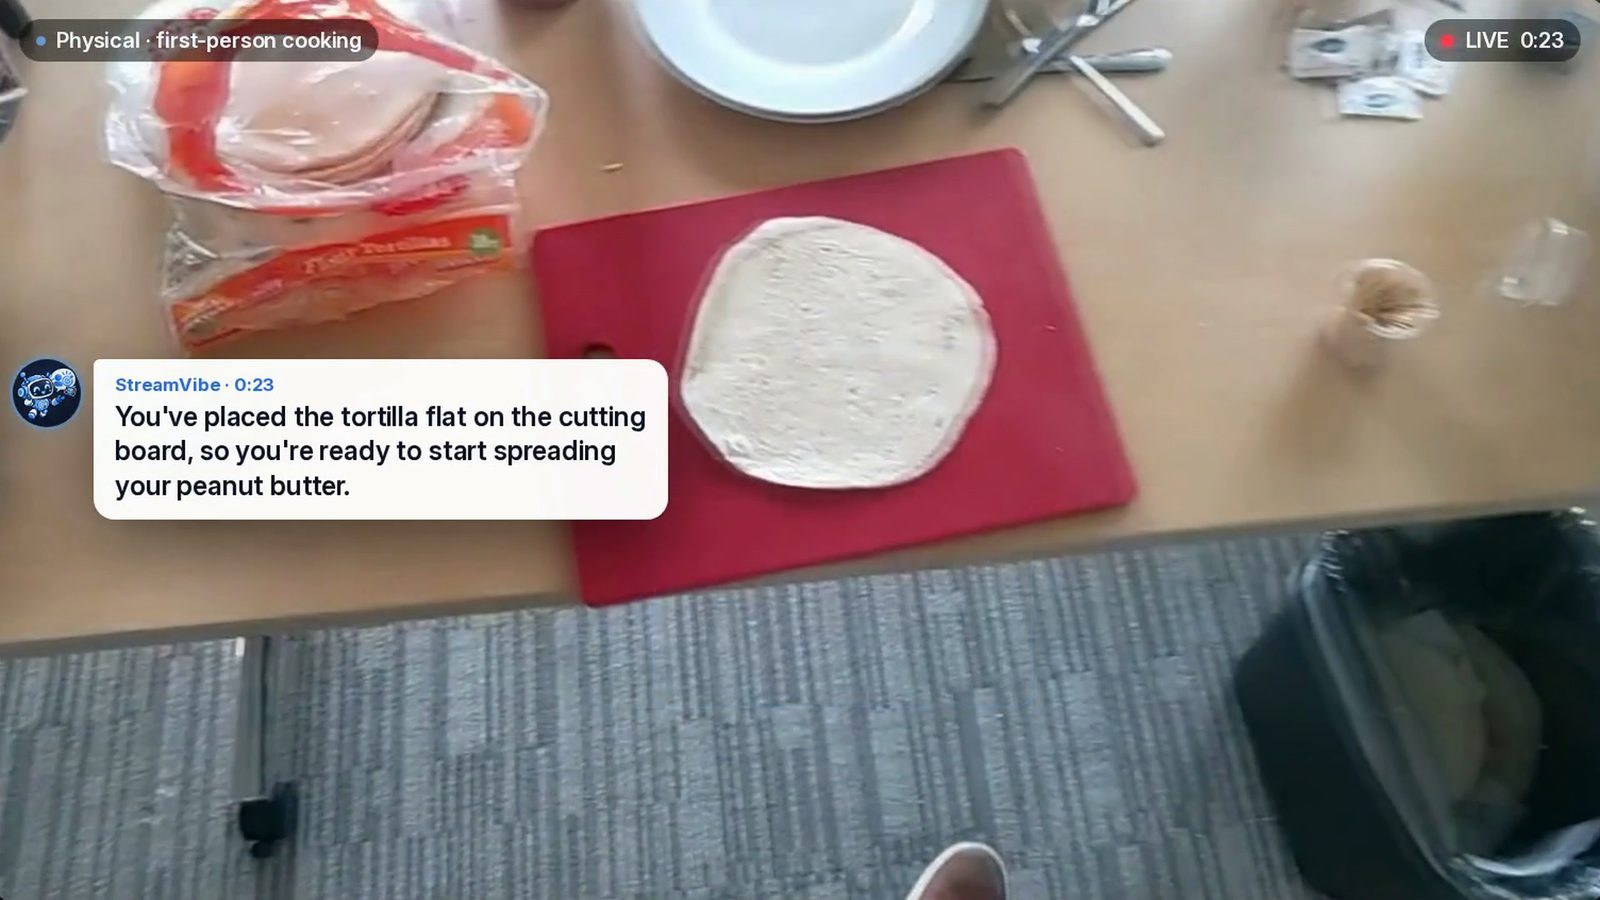
Google-led team introduces StreamVibe video agent for timely assistance
A Google-led research team has introduced StreamVibe, a video agent designed to decide when to speak up during tasks. Tests show gains in response timing and quality, but also persistent weaknesses in long videos.
A research team led by Google has introduced StreamVibe, a video agent designed to decide for itself when to speak up while a user works. The project brings together researchers from Google, Stanford, Oxford, and several U.S. universities to build an assistant that can watch activities such as cooking or assembling furniture and offer help only when needed. The tests show both the promise of more proactive video assistance and the difficulty current models still face.
Why existing assistants fall short
According to the paper, existing video assistants are built for clear-cut commands such as "Let me know when the water starts boiling," so they rarely pick up on unspoken intentions. They also struggle to track what has already been done, which can cause repeated advice or late responses. When users change requests midway through a task, the assistants often stick to the original instructions. StreamVibe is designed to distinguish between explicitly stated, unspoken, and changing user intentions during a task.
Benchmark and training
To measure the problem, the team compiled a benchmark of about 4,100 examples from more than 183 hours of everyday life and software recordings. Gemini 2.5 Flash suggested when to offer help and what to say, while four human evaluators had to unanimously approve each example. The test covers clear instructions, vague goals, and requests that change over time. In one example, a user taking apart a toy excavator asks for progress updates and then switches to a quality check after three minutes.
The researchers trained StreamVibe-VL, a model apparently based on Alibaba's Qwen3.5-9B that decides every second whether to stay quiet or speak. A second training stage uses reinforcement learning to make the model more reserved so it does not constantly interrupt. A separate memory system tracks pending requests and completed steps, though the model alone decides whether to speak and what to say.
Results and limits
According to the researchers, StreamVibe-VL improves response timing and quality by 10.7 percent over other models, while the memory system is designed to boost proactive interaction by another 12.3 percent and cut down on unnecessary interruptions. StreamVibe-VL generally beats its base model and other open-source models by a wide margin, though Google's proprietary Gemini 3.8 Flash scores higher in several tests. As video length increases, the models are significantly less likely to time their responses correctly.
Models often make the right call when they only have to decide at specific moments whether a prompt is appropriate. But when they process an entire video and build on their own earlier responses, performance across all tested systems plummets as errors compound, and a key content metric drops by up to 61.5 percent based on the system's own history. In videos longer than five minutes, the models rarely pick the right moment and find it especially hard to track a changed instruction over a long stretch.
In a GIMP tutorial on converting a photo to black-and-white, the comparison model JoyAI says the finished image has already been saved even though the user has not opened it, while StreamVibe-VL gives the next step such as "Colors" and then "Desaturate." The researchers acknowledge that real-world situations are likely more complex than their test setup, and future work will examine how user preferences and the environment influence each other over time.
Sources: The Decoder
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.