Kimi K3 arrives with 2.8 trillion parameters and a 25-cent pelican
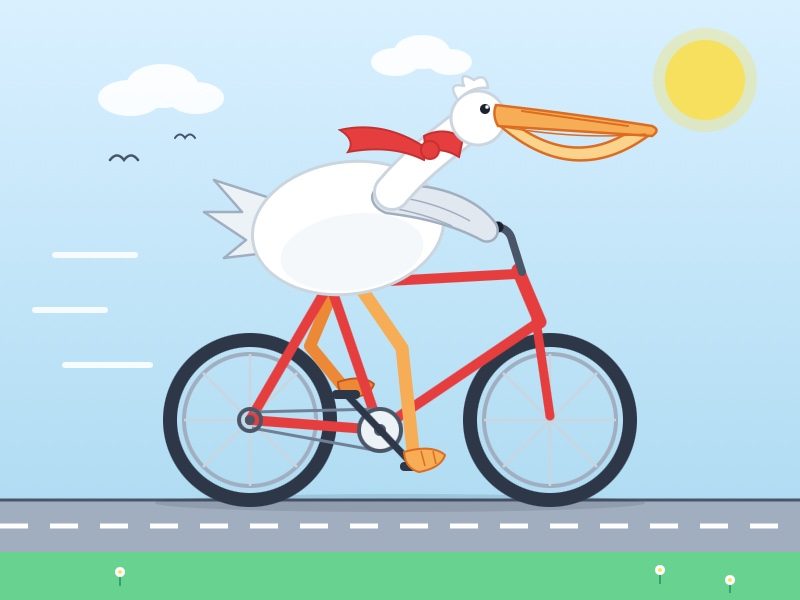
Moonshot AI has announced Kimi K3, a 2.8-trillion-parameter model it calls the first open 3T-class system, with open weights promised by July 27. Its pelican-on-a-bicycle test cost 25 cents.
Chinese AI lab Moonshot AI announced Kimi K3 on Thursday, describing it as its “most capable model to date, with 2.8 trillion parameters”. The model is available through the company’s website and API, with an open-weight release promised “by July 27, 2026”.
Positioning and price
Moonshot calls K3 the first “open 3T-class model”, rounding 2.8 trillion up to three trillion and taking that label from DeepSeek’s 1.6T v4 Pro. Its self-reported benchmarks put K3 ahead of Claude Opus 4.8 max and GPT-5.5 high in most comparisons, while trailing Claude Fable 5 and GPT-5.6 Sol. Independent evaluator Artificial Analysis measured an Elo of 1547 on its private long-horizon knowledge work test — 732 points above Kimi K2.6 and behind only Claude Fable 5 — at $0.94 per task, against $1.04 for GPT-5.6 Sol and $1.80 for Opus 4.8. Token use on its Intelligence Index fell 21% versus K2.6. The model also leads Arena.ai’s Frontend Code arena, ahead of Claude Fable 5.
Pricing is the notable change: $3 per million input tokens and $15 per million output tokens, in line with Anthropic’s Claude Sonnet series and the highest yet from a Chinese lab — a sharp rise from Kimi K2.6 at $0.95 and $4.
How it handles a pelican on a bicycle
Simon Willison, who has run his pelican-on-a-bicycle SVG prompt against new models for 21 months, generated one with K3 through OpenRouter. The run used 95 input tokens and 16,658 output tokens, 13,241 of them reasoning tokens, for a total of 25 cents. Given the rendered image as input, the model described it accurately for about 0.6 cents. The prompt also showed that K3 currently offers only one reasoning effort level, “max”, and that a bare “hi” is billed at 86 tokens, implying a hidden system prompt of roughly 85 tokens that the model declined to reveal.
What the test still tells us
Willison is explicit that the pelican is a poor benchmark and should not be used to rank models: it says nothing about agentic tool calling or reliability in long conversations, and its earlier correlation with model quality has broken down — the GPT-5.6 and Claude Fable 5 pelicans are outclassed by GLM-5.2. Its value is narrower: it forces him to actually run a model, gives a rough estimate of cost and reasoning effort, confirms valid SVG output and basic spatial sense, and allows comparisons within a model family, where K3’s bird is a clear improvement on Kimi 2.5.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.