Month-long GLM 5.3 Flash challenge ends with 50% usage
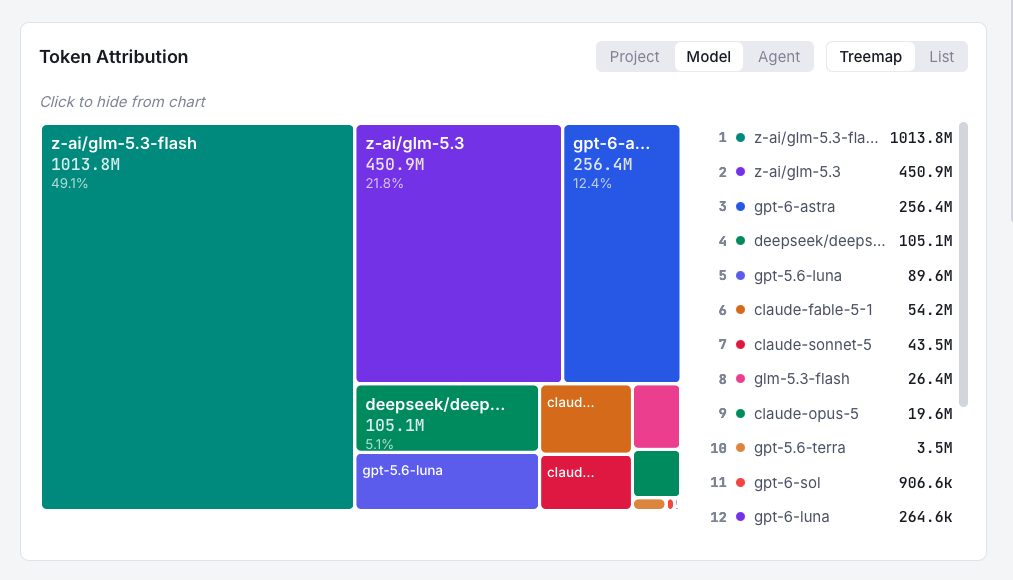
A month-long effort to use GLM 5.3 Flash for all AI work ended with half of 2B tokens handled by the target model. Tests also exposed prototype costs, provider capacity limits, and the value of measuring efficiency.
Usage split and prototype costs
An experiment to spend September using a single efficient open model produced a 50% adoption rate. Only 1B of 2B tokens were processed with GLM 5.3 Flash, although it handled all work during the first half of the month. Its reported usage remained within a budget of $68, about 4kWh of energy and 365 grams of carbon emissions. The second half required 1B tokens on other models.
One surprise came from an experimental Wagtail MCP server described as a vibe-coded prototype. The model choice resulted in 450M tokens, $150 and 5kWh of energy use being spent almost overnight. The server worked well and demonstrated its capabilities, but the team estimated that similar results might have been achieved at one-fifth of the cost with little additional effort. The episode reinforced the need to budget experiments and choose models carefully.
Infrastructure availability
Provider availability was another problem. The inference providers used by the team often worked, but popular choices did not have the same capacity as large labs. GLM 5.3 Flash showed degraded performance, likely because it sat high on the Pareto frontier for the team's work. The available selection was also limited to open models confirmed in European data centers. This prompted switches to similar models, DeepSeek V4.1 Flash and Qwen 3.8 Flash, a simple change that had not been expected.
Value for routine development work
Running one model for routine engineering did not remove the need to test a broad range of offerings. The team is beginning to benchmark models on Wagtail tasks and needs comparable data to recommend leaner options for agent skills and a new CLI prototype intended to work well with agents.
GLM 5.3 Flash was still rated excellent for production work due to its 1M-token context window, vision support and availability across multiple providers. It was used on Wagtail and sites built with it, as well as for UI tasks, AI research and development, documentation and evaluations.
Lessons for the next test
For October, the challenge will continue only for routine production work, not research and development. The planned changes include continuous local reporting of token use, energy consumption, spending and concrete outcomes. The team also plans to set explicit experiment budgets, improve prompt selection, use role-based multi-agent workflows and continue testing efficient models.
The broader goal is for most AI inference work to use one or two inexpensive flash-tier models, with progress judged by cost or energy use rather than token counts alone. The team will also watch Jev-style decision diffusion models if they can run efficiently, while newer flagship models appear to be a step in the right direction.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.