Qwen 3.8 27B: excellent at 17 GB, but it overthinks by default
Alibaba's Qwen lab released a 27-billion-parameter vision model under Apache 2.0. It handles vision, code and tool calls on consumer hardware, yet its default reasoning setting wastes huge amounts of compute.
On August 14, Alibaba's Qwen research lab released Qwen 3.8 27B, a 27-billion-parameter, vision-capable language model published under the Apache 2.0 licence. The weights are available on Hugging Face, and the model can be run locally through LM Studio or llama.cpp.
Benchmarks and first impressions
Qwen's self-reported results put the new model clearly ahead of its predecessor, Qwen 3.6 27B, and even past the closed-weight Qwen 3.7-Plus — a system that ranked among Qwen's strongest models of any size as recently as May. Independent evaluations have not been published yet. Developer Simon Willison, who tested the model on a 128 GB M5 Max MacBook Pro and an NVIDIA DGX Spark, described 27B as an excellent size for running a capable model on a normal laptop.
Overthinking is the default
The model exposes a reasoning_effort parameter whose default value is "xhigh", and the LM Studio GGUF build keeps it. In practice that means even trivial requests consume thousands of reasoning tokens: LM Studio's default 8,192-token context was quickly exhausted, and the problem disappeared only after loading the full 262,144-token context.
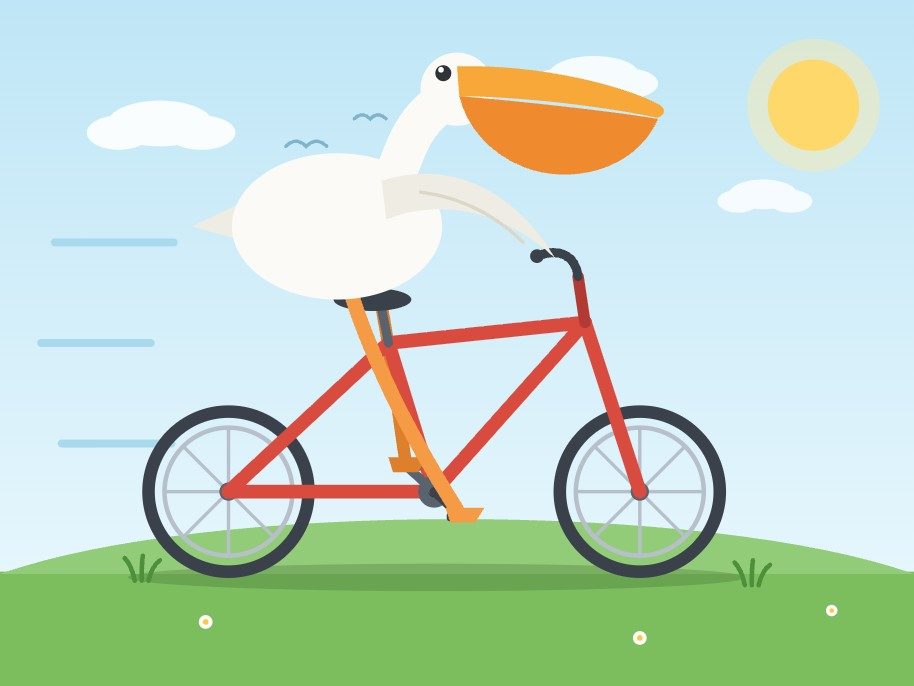
In a test, the model needed 21 minutes and 22,276 reasoning tokens to produce 3,223 tokens of SVG output — a pelican riding a bicycle. With reasoning switched off, the same prompt finished in 137 seconds and 3,715 tokens. Asked simply to "draw an svg of a circle", the model answered with an elaborate animated composition. The author's practical advice is to run the model at the low setting, or with reasoning off, at least at first.
Vision, tool use and speed
The model turned out to be strong at visual grounding: asked for JSON bounding boxes on a 0–1000 scale for pelicans in a photograph, it returned coordinates that matched the objects closely. Given a single prompt, it also built a small HTML tool for drawing such boxes over an image, running entirely offline; the result was heavily over-engineered but functional.
The main drawback is speed. LM Studio delivered roughly 15–30 tokens per second, against 74 and 184 tokens per second measured by Artificial Analysis for OpenAI's hosted 5.6 Sol and 5.6 Luna. A community optimisation helps: Qwen supports Multi-Token Prediction, and a llama.cpp server started with the draft-mtp speculative decoding option outperformed the default LM Studio build by about 72% in a benchmark on the DGX Spark.
The wider point is what a 17 GB file now demonstrates: long context, tool calling, vision and competent code generation, all on hardware a developer already owns. The open question is whether inference speed can catch up.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.