NVIDIA and IIT Madras Release 2.8 Trillion Token Indic Pretraining Corpus
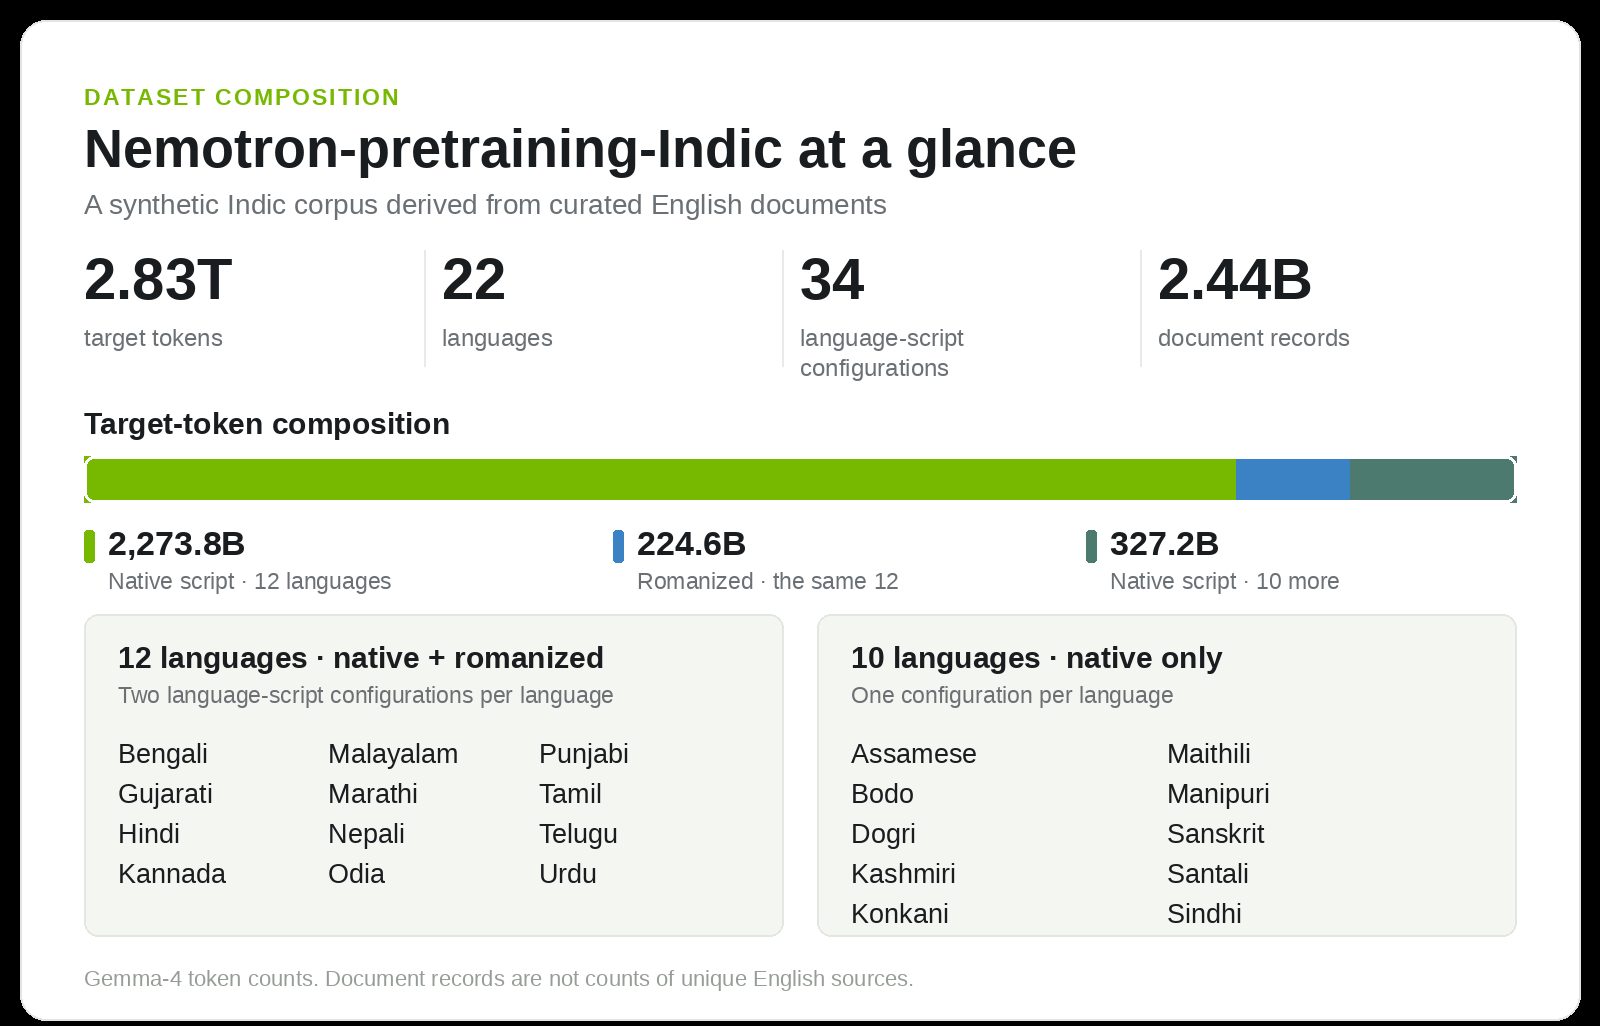
NVIDIA, IIT Madras and AI4Bharat are releasing Nemotron-pretraining-Indic-v1, a corpus of about 2.8 trillion tokens across 22 Indian languages, along with the open GPU-accelerated pipeline used to generate it.
A Corpus for 22 Indian Languages
NVIDIA, together with IIT Madras and its AI4Bharat lab, has introduced Nemotron-pretraining-Indic-v1, a pretraining corpus of approximately 2.8 trillion tokens spanning the 22 languages listed in India's Constitution. The release also includes the open, GPU-accelerated data generation pipeline used to create it, covering translation, quality assessment, and repair.
The corpus contains 2,601.0 billion native-script tokens and 224.6 billion romanized tokens, counted with the Gemma-4 tokenizer. It covers 34 language-script configurations: native-script data for all 22 languages and romanized text for twelve of them. Every record traces back to a curated source document, and each output is checked against its input so the synthetic text stays grounded in real information.
From English Sources to Indic Training Data
The pipeline starts from documents in 15 Nemotron-CC-v2 subsets, spanning web text, question-answer material, mathematics, code, and other specialized content. NVIDIA's open-source NeMo Data Designer framework runs the translation, quality checks, and targeted repair, retaining source identifiers so outputs can be traced to their original documents.
For twelve languages, documents are translated in full using Gemma-4-31B-it, which was selected after comparing models on complete documents. A rubric inspired by Multidimensional Quality Metrics covers meaning, fluency, terminology, style, and formatting, and only outputs scoring at least 75 out of 100 are retained. Lower-scoring outputs are repaired using the assessment feedback and reassessed, a process that recovered 438.4 billion tokens. Accepted native-script translations are also converted into Latin script for the romanized portion.
The remaining ten languages use a separate workflow built around Indic Translate, a document-level translation model from Bodhan AI. For longer Santali documents, overlapping windows are translated and reconstructed; for Manipuri, text is translated into Bengali script before conversion to Meitei Mayek.
Impact on Nemotron Models
Continued pretraining for Nemotron 3.5 Super VL added 10 billion Indic tokens drawn from a twelve-language subset of the corpus and natural Indic text. Scores increased on all five reported Indic knowledge and reasoning benchmarks, with gains ranging from 4.98 to 9.82 percentage points. The released model also scores higher than Nemotron 3 Super on five of six Indic task benchmarks and improves across all four IndiVibe dimensions, though instruction following on IFEval 1.5 dipped 2.04 points.
The team plans to build on this corpus in future Nemotron models and recommends combining it with naturally authored Indic text for local knowledge and cultural context.
Sources: Hugging Face Blog
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.