AWS ships WhisperX container for speaker-labeled transcription on SageMaker AI
AWS has published a walkthrough for running WhisperX on Amazon SageMaker AI, adding per-word timestamps and speaker diarization to OpenAI's Whisper speech recognition model.
AWS has published a walkthrough for running WhisperX, the open source speech-to-text project built on OpenAI's Whisper, on Amazon SageMaker AI. The post presents the AWS WhisperX Deep Learning Container and two ways to serve it, from a real-time or an asynchronous endpoint.
What WhisperX adds to Whisper
Whisper transcribes many languages accurately, but it returns timestamps at the phrase level and never says who is speaking. WhisperX adds three things: batched inference for faster transcription, wav2vec2 forced alignment for per-word timestamps, and speaker diarization that labels each voice.
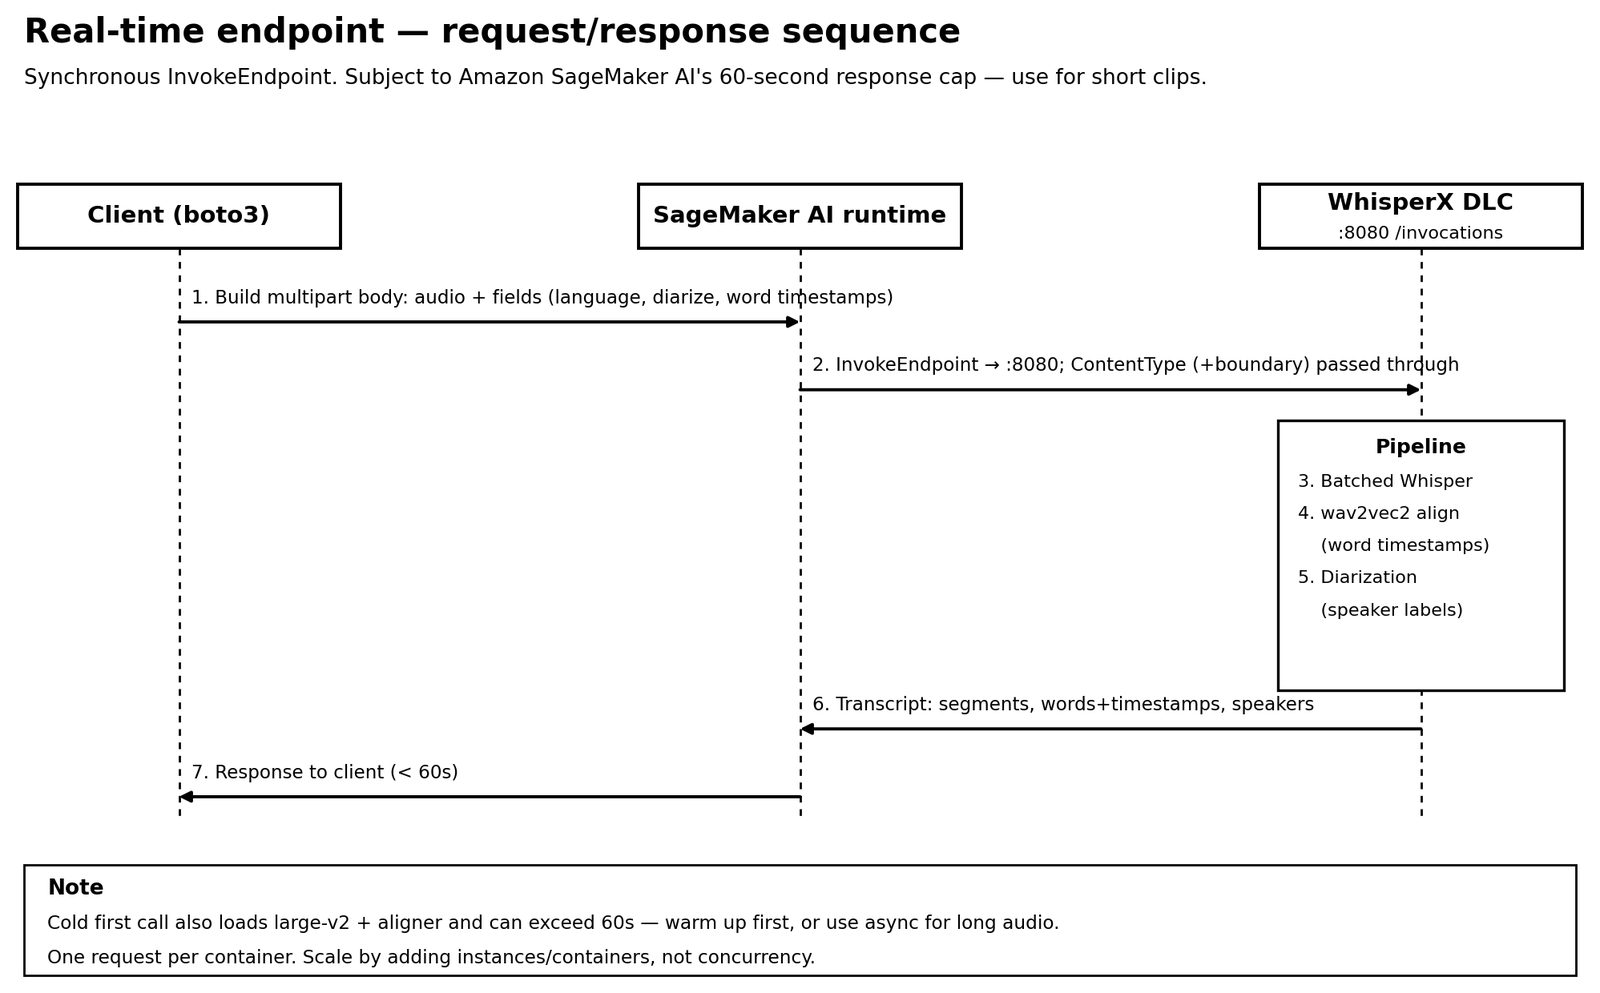
The container packages Whisper, the alignment models and the diarization weights in one GPU-ready image, so no Hugging Face token is required. It serves on port 8080, exposes POST /invocations and GET /ping, accepts multipart/form-data with the audio file and fields such as language and diarize, and returns json, verbose_json, srt or vtt.
Real-time or asynchronous endpoints
A real-time endpoint is synchronous: audio goes in the request and the transcript returns in the same call, so a clip must finish inside the SageMaker AI 60-second cap. It bills while it stays up.
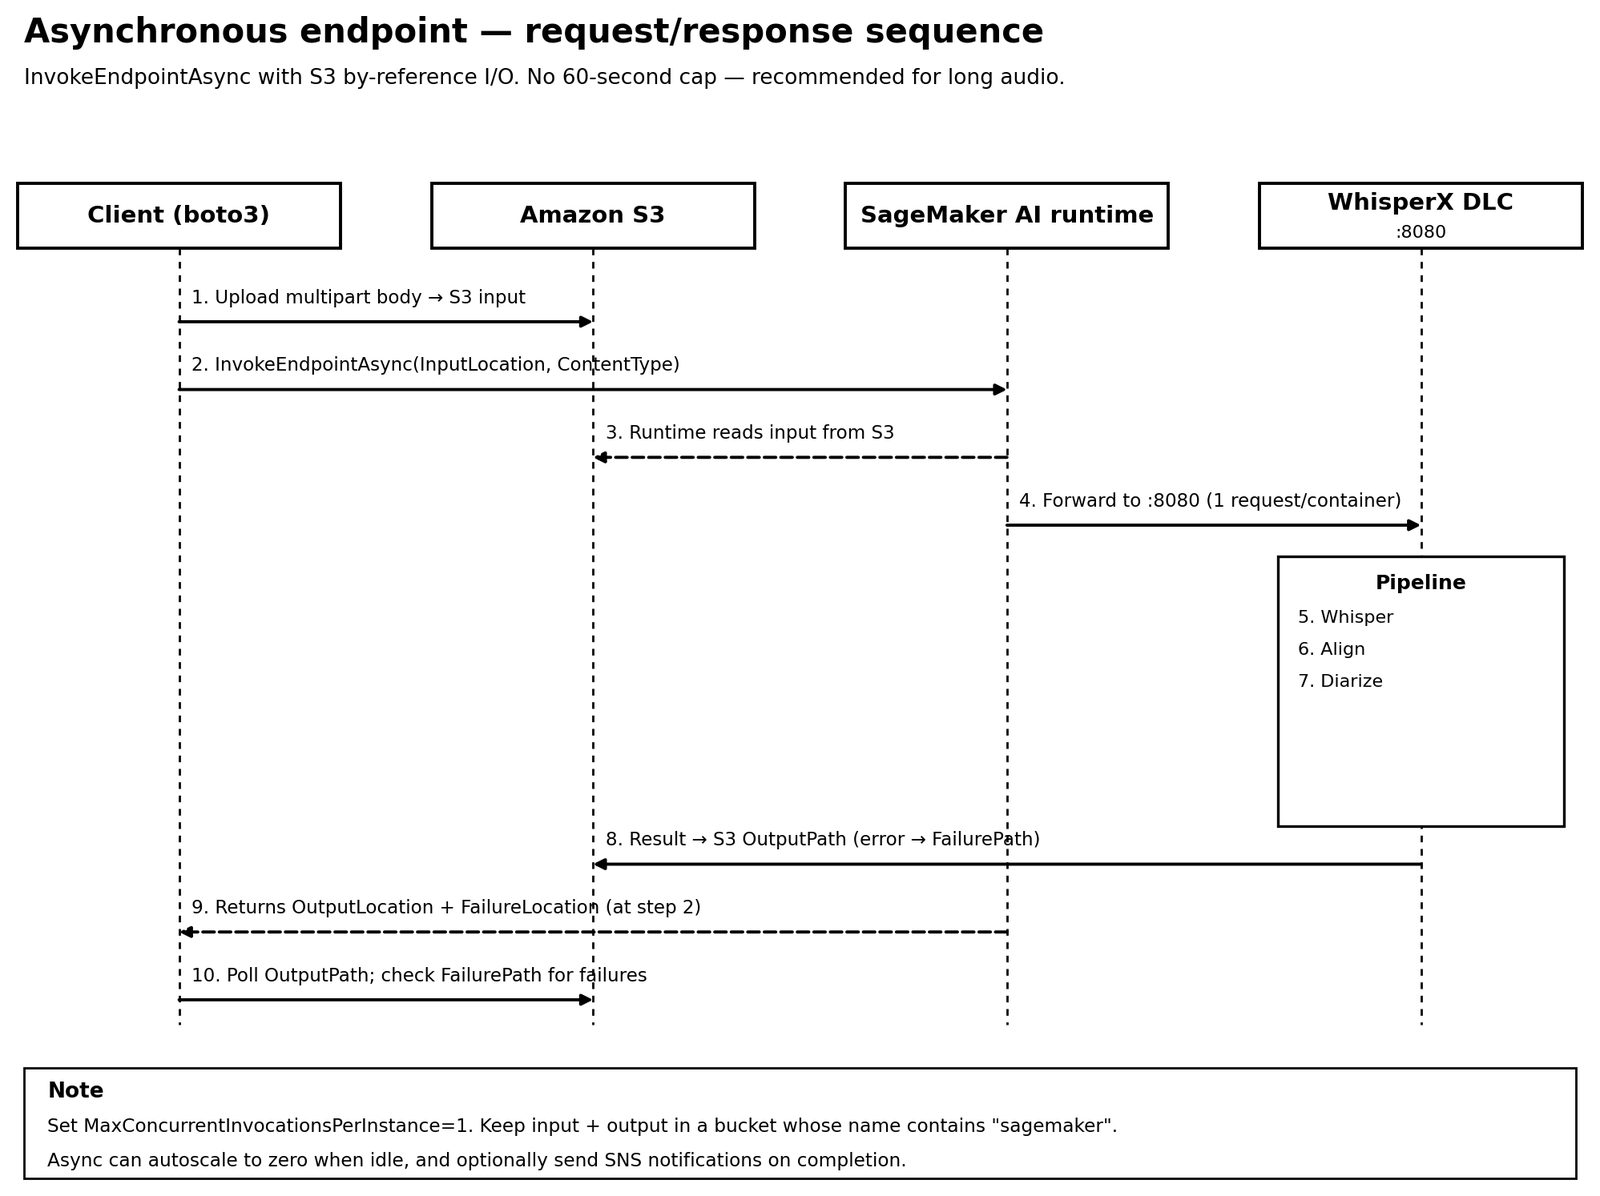
An asynchronous endpoint uploads to Amazon S3, calls InvokeEndpointAsync by reference and polls the output path, with a separate failure path for failed jobs. There is no response cap, which makes it the route AWS recommends for long recordings and batch work, and it can scale down to zero when idle.
Production details and the Flight 1549 test
Both patterns need the same pieces: ml.g4dn.xlarge for cost or ml.g5.2xlarge for headroom, and the GPU AMI pin al2-ami-sagemaker-inference-gpu-3-1, without which the CUDA 12.8 image returns a zero-log CannotStartContainerError. Inference runs one request per container, so throughput comes from adding instances, and asynchronous buckets must carry sagemaker in their name.
The companion notebook transcribes a public-domain recording of the air traffic control exchange from US Airways Flight 1549, the 2009 emergency landing, with its radio noise and fast callsigns: three minutes to the asynchronous endpoint and 40 seconds to the real-time one. AWS also advises SNS completion notifications instead of tight polling, instance pools of up to five instance types, S3 Block Public Access, and redaction downstream using word-level timestamps. GPU endpoints bill until deleted.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.