NVIDIA Open-Sources NVCRE to Test GPU Clusters Before Workloads Land
The Apache 2.0 Kubernetes controller runs real distributed workloads on topology-aware node groups, measuring hardware and naming the nodes that fail before production training jobs arrive.
Healthy on paper, failing under load
A GPU cluster can pass every health check and still fail to run an AI workload: even when every GPU, link and pod reports healthy, a 512-GPU training job can underperform. The cause may be one slow GPU, a link that degrades under load, or a configuration that quietly routes traffic over a slower path.
NVIDIA Cluster Readiness Engine (NVCRE) is an open source Kubernetes controller that narrows the search to the specific nodes involved. It runs real distributed workloads on topology-aware node groups and reports which nodes failed each test, so readiness becomes a proven property of the cluster rather than an assumption.
A layered API and a built-in catalog
The API has three resources: a Certification names the nodes and categories to test; each category gets a Workflow that applies platform and GPU overrides and creates a child Job; the Job runs the workload, monitors node health and attributes failures to specific nodes.
The catalog covers five NCCL communication variants, the NVIDIA DCGM level-4 diagnostic suite and NVIDIA NeMo pretraining with Nemotron 5 models. Pass criteria are written in the Common Expression Language, and a job that finishes but misses its target still counts as a failure.
Testing at the scale where failures appear
The testScale field picks the grouping strategy: intra-node, intra-rack (partitioned by the nvidia.com/gpu.clique label), full-scale or diagnose. In diagnose mode NVCRE splits failing groups and reruns the halves until it names a few suspect nodes instead of the whole group.
WorkloadRun runs multi-node jobs from a container image, a framework choice (torch, mpi or exec) and a node count. Setting spec.gangScheduler opts pods into a gang-aware scheduler such as KAI Scheduler, avoiding deadlocks on busy clusters.
Detect, verify, remediate
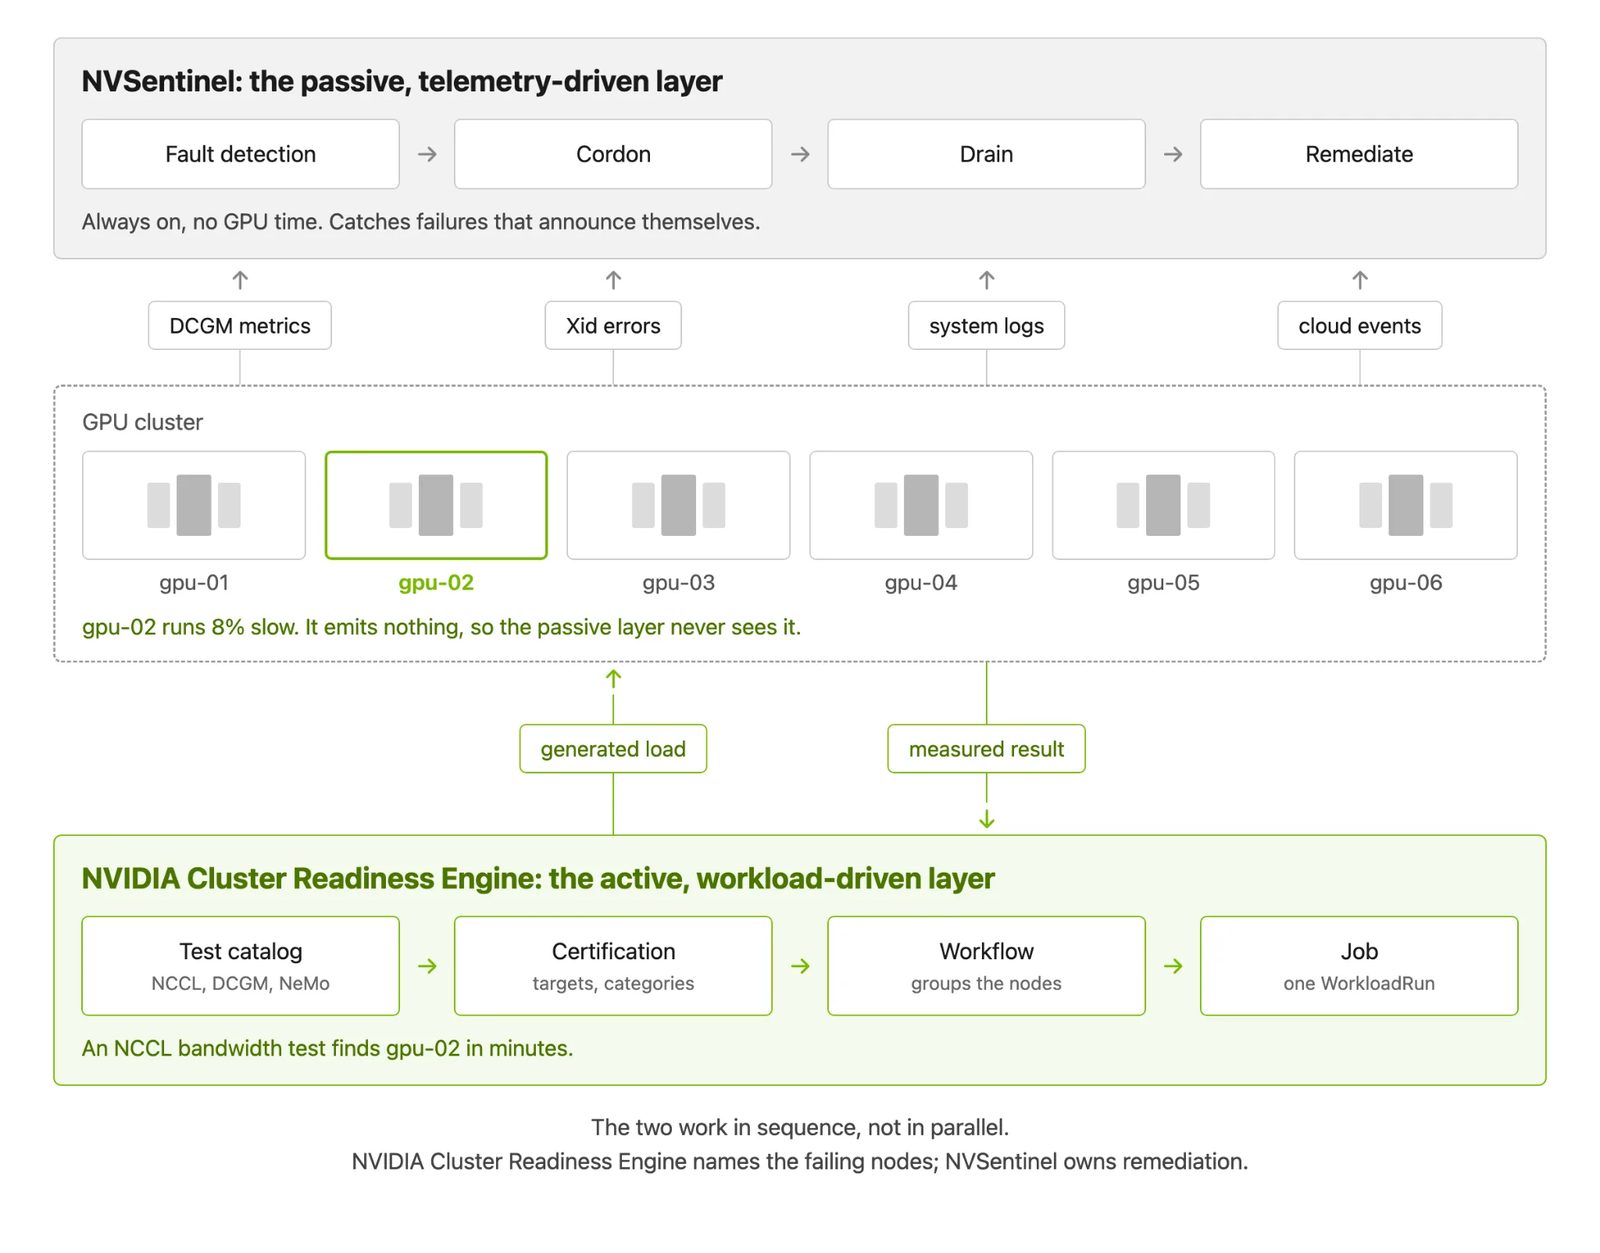
NVCRE is one layer of NVIDIA DSX OS: AICR keeps a validated configuration and detects drift, NVCRE generates load to expose failures the telemetry never shows, and NVSentinel watches DCGM metrics, Xid errors and system logs.
NVCRE records failed nodes and reasons but does not cordon, taint or patch node conditions; the NVSentinel Certification Monitor can turn a failed certification into a health event. The project is licensed under Apache 2.0 and requires Kubernetes 1.29+, kubectl, Helm 3.x and the NVIDIA GPU Operator.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.