Embedding Gemma Transcribe Turns Google's EmbeddingGemma 2 Into On-Device Speech-to-Text
A new free Mac app converts Google's EmbeddingGemma 2 into a speech-to-text model, transcribing an hour of audio in about 13 seconds on a base MacBook Air using only the Neural Engine, with audio never leaving the machine.
From Embedding Model to Transcriber
Embedding Gemma Transcribe is a free Mac application that repurposes Google's EmbeddingGemma 2, a multimodal embedding model that maps text, images, audio and video into a single shared space. Because spoken words land close to their written counterparts in that space, the developers read words directly out of it to produce transcripts.
The model's audio encoder is left exactly as shipped. A small reader component moves each short slice of audio into the model's text space, where the closest match among roughly 229,000 English words wins, and the sequence of slices becomes the transcript. A separate tiny model adds punctuation and capitalization. Only the reader was trained, for under two hours on 8×H100 GPUs using openly licensed English speech. The base model itself was never trained for speech-to-text.
Speed on Apple Silicon
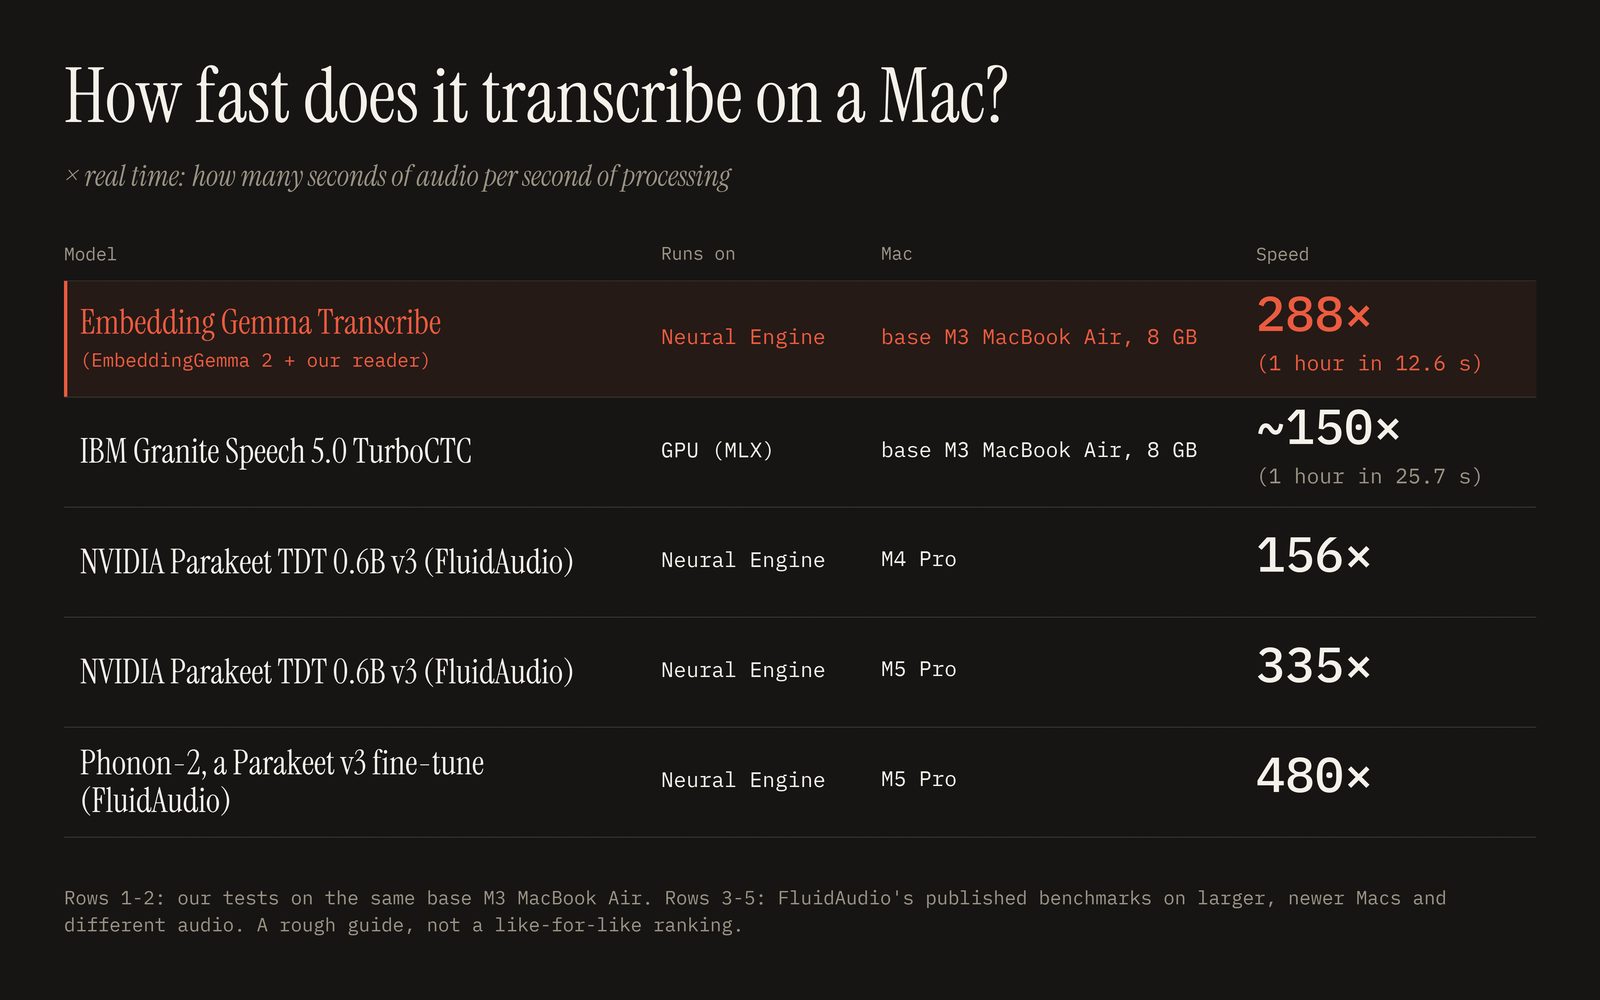
According to the developers' tests, the app runs entirely on a Mac's Neural Engine. On a base M3 MacBook Air with 8 GB of memory, it processed one hour of audio in 12.6 seconds, a speed the team lists as 288 times real time. In the same test setup, IBM Granite Speech 5.0 TurboCTC running on GPU through MLX took 25.7 seconds, about 150 times real time.
The team also cites published FluidAudio benchmarks for comparison: NVIDIA Parakeet TDT 0.6B v3 reached 156 times real time on an M4 Pro and 335 times on an M5 Pro, while Phonon-2, a Parakeet v3 fine-tune, reached 480 times on an M5 Pro. The developers note those figures come from larger, newer Macs and different audio, so the table is a rough guide rather than a like-for-like ranking.
Accuracy and Availability
The current word error rate is about 5%, compared with 2-3% for leading speech models. The team believes a better-trained reader can close that gap and describes it as the focus of the next iteration.
Version 1.6 requires macOS 14 or later and Apple Silicon, with the 715 MB model downloading on first launch. Users can drop in an audio file or hold the Right Option key, speak, and release to dictate into any app. Because processing happens on the Neural Engine, audio never leaves the machine. The app is available as a free download for Mac.
Sources: eg2.haku.sh
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.