AWS shows an agentic architecture for conversational video intelligence
AWS Machine Learning Blog has published the architecture of a video intelligence solution that answers natural-language questions about uploaded recordings, orchestrating Amazon Bedrock, Amazon Rekognition and Amazon Transcribe at runtime.
Teams in media, security, insurance and professional services record far more video than they can watch: meeting recordings pile up in shared drives and cameras capture weeks of unreviewed footage. The details inside — a decision from weeks ago, the moment a person arrived at a door — normally require hours of watching to find.
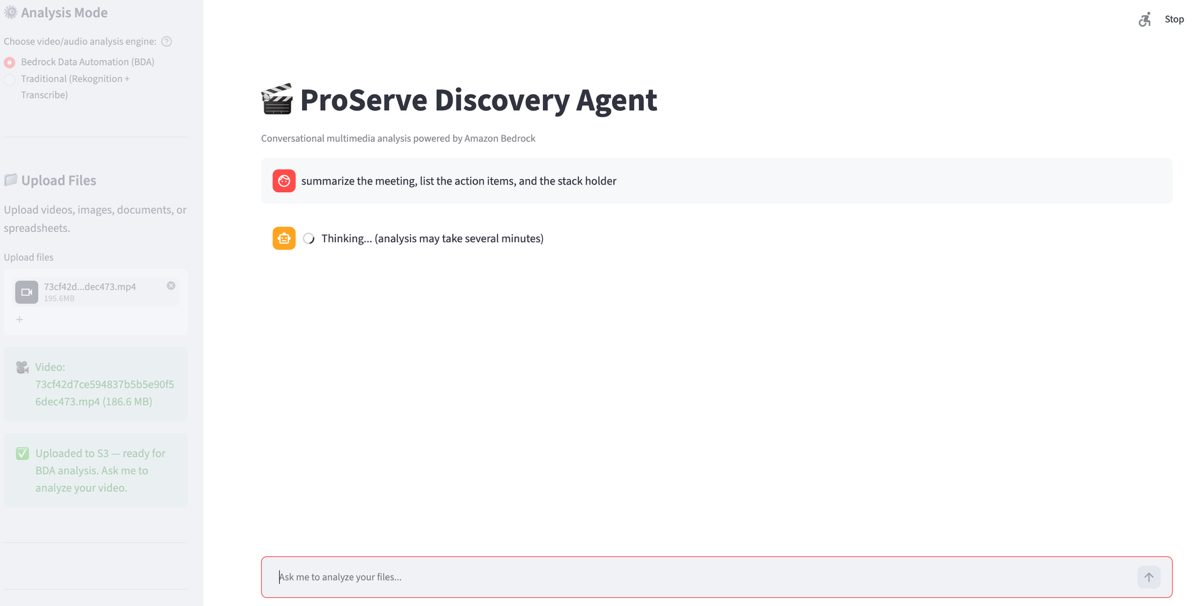
AWS Machine Learning Blog has published the architecture of a solution that makes that content queryable in natural language. A user uploads a recording and asks “What decisions were made in this meeting?”; the system answers with timestamps. Previously analysed content returns an answer in under a second, while the first analysis of a new video takes 5–10 minutes.
One agent instead of fixed pipelines
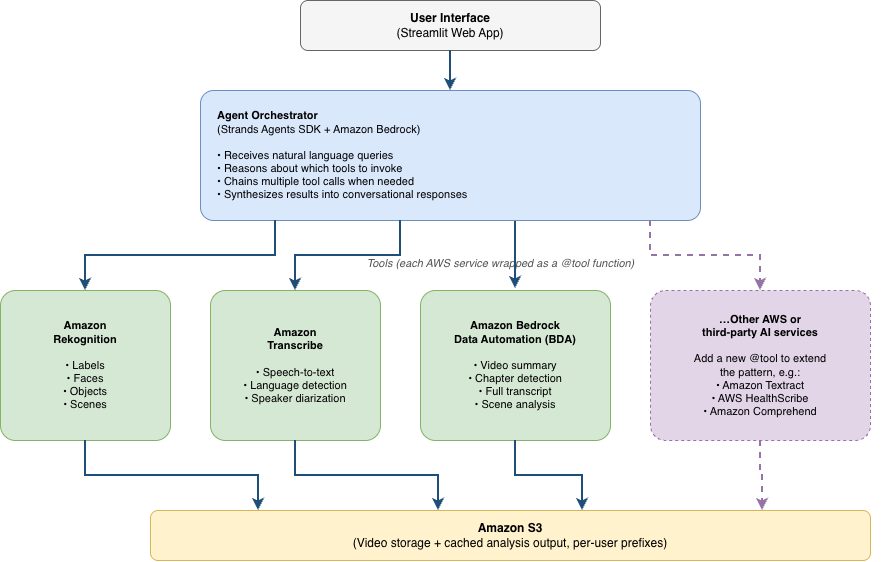
The core is the Strands Agents SDK. Instead of a pre-built pipeline per question type — transcription, visual search, face matching — a single agent decides at runtime which services to call: spoken-content questions go to Amazon Transcribe, visual ones to Amazon Rekognition, with Amazon Bedrock as the reasoning layer. Results are cached in Amazon S3, so follow-up questions reuse earlier analysis.
Results and use cases
Each AWS service is exposed as a Python function decorated with @tool, and its docstring tells the model when to use it. For a face-match query the agent chains two dependent steps — index a reference photo, then search the footage — reporting times and confidence scores.
A media and entertainment company adopted the approach in an AWS Professional Services project, querying recorded discovery sessions. By the customer’s internal before-and-after comparison, manual review time fell by roughly 80% across a backlog of more than 200 multi-hour recordings; AWS notes the figure was not independently verified.
Deployment, cost and limits
The reference implementation runs on Amazon ECS with AWS Fargate behind an internal load balancer reachable only through Amazon CloudFront. Access is invitation-only, via Amazon Cognito accounts with mandatory multi-factor authentication, and uploads stay in per-user S3 prefixes with a 24-hour lifecycle.
A 60-minute video costs about $1.44 to transcribe and $0.05–0.15 per follow-up question, with face or label analysis around $6 one-time. Because the agent picks tools from their descriptions, Amazon Textract, AWS HealthScribe or Amazon Comprehend can be added without workflow changes.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.