OpenAI improves prompt caching for the GPT-6 family
OpenAI has detailed an improved prompt caching system for its GPT-6 model family: higher cache hit rates by default, discounts of up to 90 percent on cached input tokens and new tools to diagnose misses.
OpenAI has detailed an improved prompt caching system for its GPT-6 model family, saying it lifts cache hit rates by default and gives developers discounts of up to 90 percent on cached input tokens. The update appeared on September 22, 2026.
Caching matters most for agents that run for hours on complex work, from refactoring codebases to producing researched documents. Those applications send long series of API requests carrying the same instructions, tool definitions and earlier context, so reusing computation instead of repeating it cuts both latency and cost.
Higher hit rates by default
With GPT-6, OpenAI says eligible shared prefixes are discounted when they are reused inside a 30-minute window. The system is automatic, but the company also added tools that let teams measure what is actually being reused.
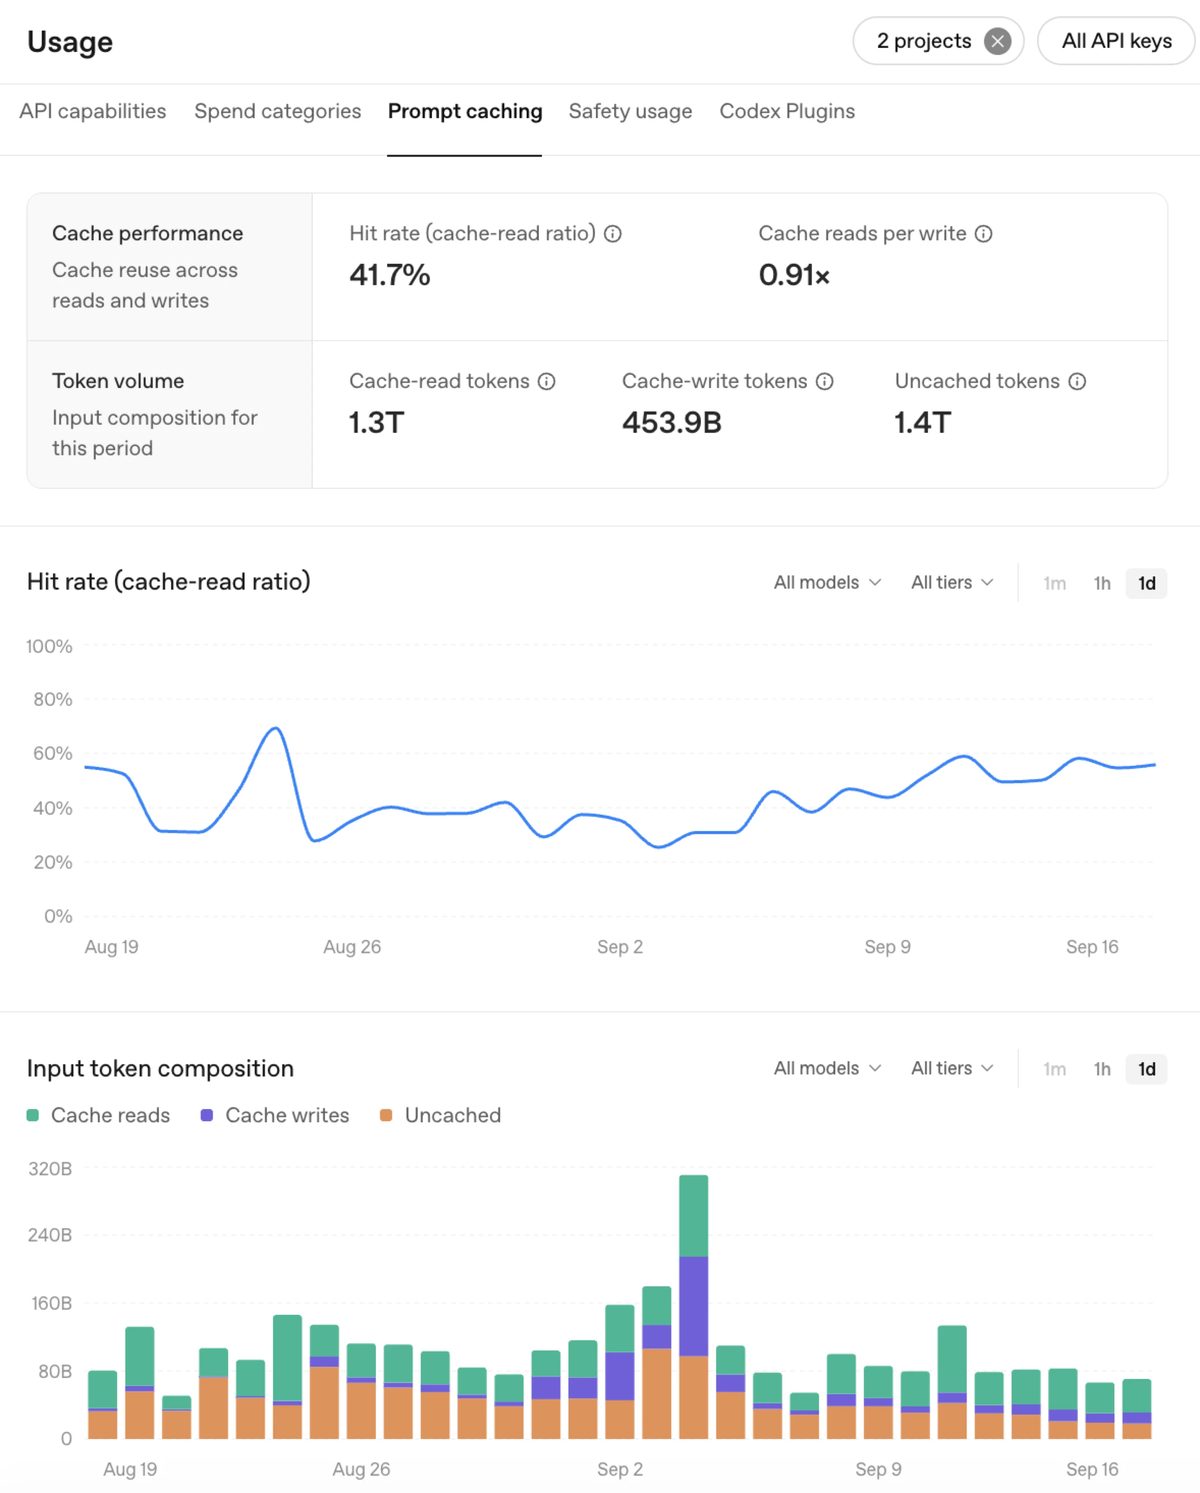
The new Prompt Caching Dashboard shows how much of an application's input comes from cache, tracks hit rates over time and compares cached with uncached tokens. When a miss looks unexpected, a diagnostics tool compares a request with a recent response and names the cause — a changed model, tool set, setting or input — while estimating the tokens affected. In OpenAI's example, a tools_changed miss left 5,629 reusable tokens unclaimed.
Controls for developers
Explicit cache breakpoints let developers choose which prefixes to reuse, and OpenAI refreshed its prompt caching guide with the details. On GPT-6 models, reasoning effort can now change between responses by appending a configuration_update, leaving request-level effort untouched so the cache survives.
OpenAI also advises keeping tool definitions, schemas and ordering stable: expose only the needed tools with allowed_tools, or set tool_choice to none, rather than deleting definitions. New instructions belong in developer messages appended near the end of the context, and known context can be prewarmed before a user asks anything.
What customers report
GitHub Copilot chief product officer Mario Rodriguez said the work cut by more than 50 percent the share of prompt tokens needing fresh processing across billions of requests. Strawberry Browser CTO Arian Hanifi reported 20 percent lower costs and said explicit breakpoints made forking conversations for background tasks viable. Manus rose from roughly 85 to consistently above 90 percent in under a week, per team lead Bin Fan, while Wordsmith went from 83 to 91 percent, cutting cache writes by two-thirds and inference costs by 36 percent.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.