Essay: AI-driven development is normalizing failures nobody investigates
A widely discussed essay on the blog ihatethefuture.com argues that LLM-accelerated development is teaching builders and users alike to accept "sometimes things just suck" instead of tracing failures to concrete causes.
An essay published on the blog ihatethefuture.com (author handle: patrickxia), titled "the normalization of inexplicable failures", has climbed to the top of Hacker News. The post argues that a culture of LLM-accelerated software development is quietly normalizing failures that nobody stops to explain.
"Stupid thing sucks"
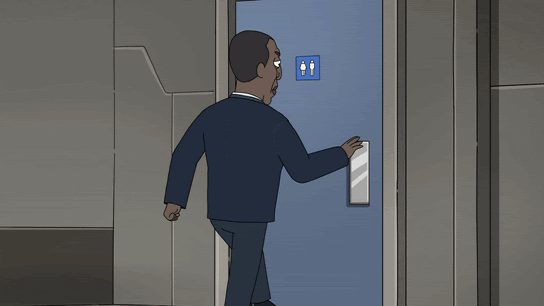
The essay opens with two cartoon GIFs of a character trying to walk through a door that will not open. The doors are obstructed: first by a body, later by "roughly a billion dollars worth of gold". In both scenes the frustrated character mutters "stupid thing sucks" and moves on. The author calls this "not a reasonable model of doors": the failure had a concrete cause, and the blame landed on the wrong object.
Jev and the "AI-powered" checkbox
The post then turns to Jev, an AI model developed by TypeSafe AI that returns typed values together with probability estimates, a design that has been an active topic among teams building AI-based products. The author sums up its selling points as speed and cost: fast, cheap, quick to build on. His concern is what happens after the build. As he tells it, buyers rarely run evaluations: they hand opaque questions to Jev, get opaque answers, and can then tick the "AI-powered" box. When a downstream system breaks, "well, AI makes mistakes" serves as the explanation, while error budgets, failure modes and test sets are deferred. Users meanwhile discover the failure rate for themselves.
The essay anticipates the obvious defense: Jev returns confidence scores. What can you actually do with one? To act on a confidence score, the author argues, you need to understand how well calibrated it is, and to have a model of what the uncertainty costs. At best, he writes, people use confidence scores in a "cargo cult" manner; at worst they cite them as an excuse for a failed call, as if a "73% confident" answer carved out a 27% error budget.
Accountability and where investigations end
When a button breaks on a website, the author notes, engineers normally have a model of what should have happened: a contract broke, DNS misbehaved, someone shipped a script with syntax errors along one path, a handler threw unexpectedly. There may be no access to debug a bare HTTP 500, but someone's job is to understand why the endpoint is failing. For many users, the lived experience is closer to "stupid thing sucks".
The essay's fear is not that LLM-driven development will produce more failures: it will, and it already has; that is part of the price of building in a novel way. The fear is that "sometimes it just sucks" becomes the accepted endpoint of the investigation itself. The author calls that a loss, because LLM-accelerated work can also help fix such problems: automated QA workflows go unwritten for lack of engineering time, and the very eval that would replace, or justify, a system like Jev "can be a few prompts away". The piece closes on its metaphor: we are engineering systems where neither the user nor the builder seems interested in checking whether there is a body behind the door.
SiTech — AI-powered web development
We build fast, modern websites and bring AI into real business workflows. Have a project or a question? We'd love to help.